Blog posts
Page 1 of 4
NVIDIA Nemotron 3.5 Transcribe Is #1 Overall on Our Speech-to-Text Benchmark
NVIDIA Nemotron 3.5 Transcribe has the lowest overall word error rate on Cekura Bench: 2.28% across public clips and private phone calls, first of 21 speech-to-text models.
Tarush Agarwal
Thu Oct 29 2026
Voice Evals That Auto-Improve From Human Feedback (2026)
Learn how to build voice evals that automatically improve from human feedback using Meta-Harness, reaching 95-100% human agreement in 4 to 6 iterations.
Satvik Dixit
Wed Oct 28 2026
Voice AI Use Cases: 9 Call Types and Where Each One Breaks
Voice AI use cases by call type, from scheduling and intake to banking, insurance, collections and dispatch, with what each agent does and what breaks.
Tarush Agarwal
Wed Oct 28 2026
'Human like voices': The Best TTS Models
The best TTS voices for AI agents in 2026, compared on naturalness and latency. How human-like speech improves conversational AI and what to test in your next voice agent.
Tarush Agarwal
Fri Oct 23 2026
Cekura Bench vs. τ-bench: Benchmarking Voice Agents the Way They Actually Run
τ-bench tests whether a model can do the task. Cekura Bench tests your deployed voice agent on real audio calls, three runs each. See how the two compare.
Sidhant Kabra
Thu Oct 15 2026
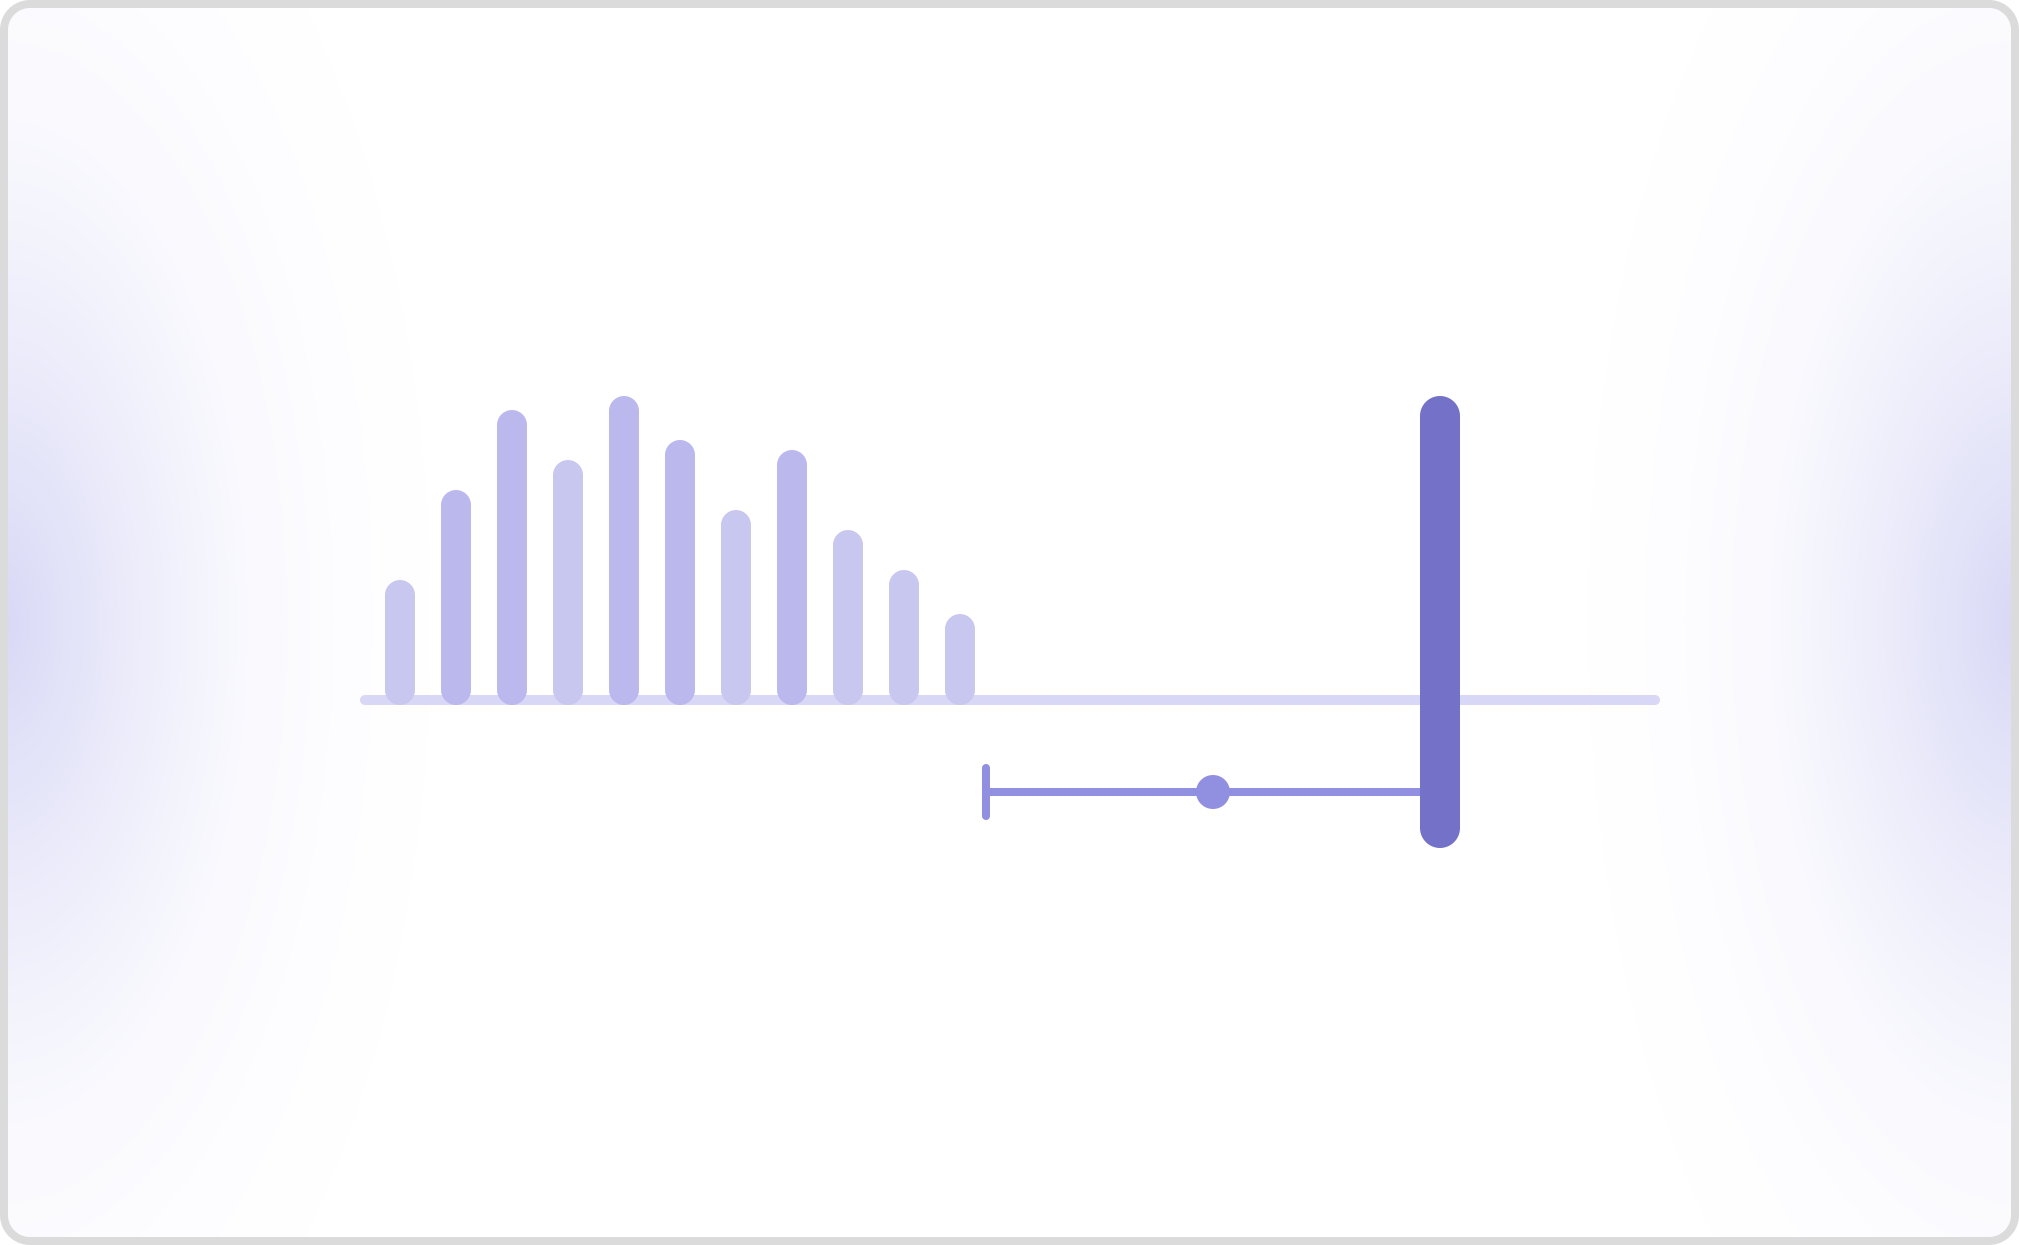
How Voice Agents Know When a Caller Has Stopped Talking
Voice agents infer turn-end from VAD and streaming STT; neither is sufficient. How Cekura's voice agent checks each close against the call's own audio.
Dileep Chagam
Wed Sep 23 2026
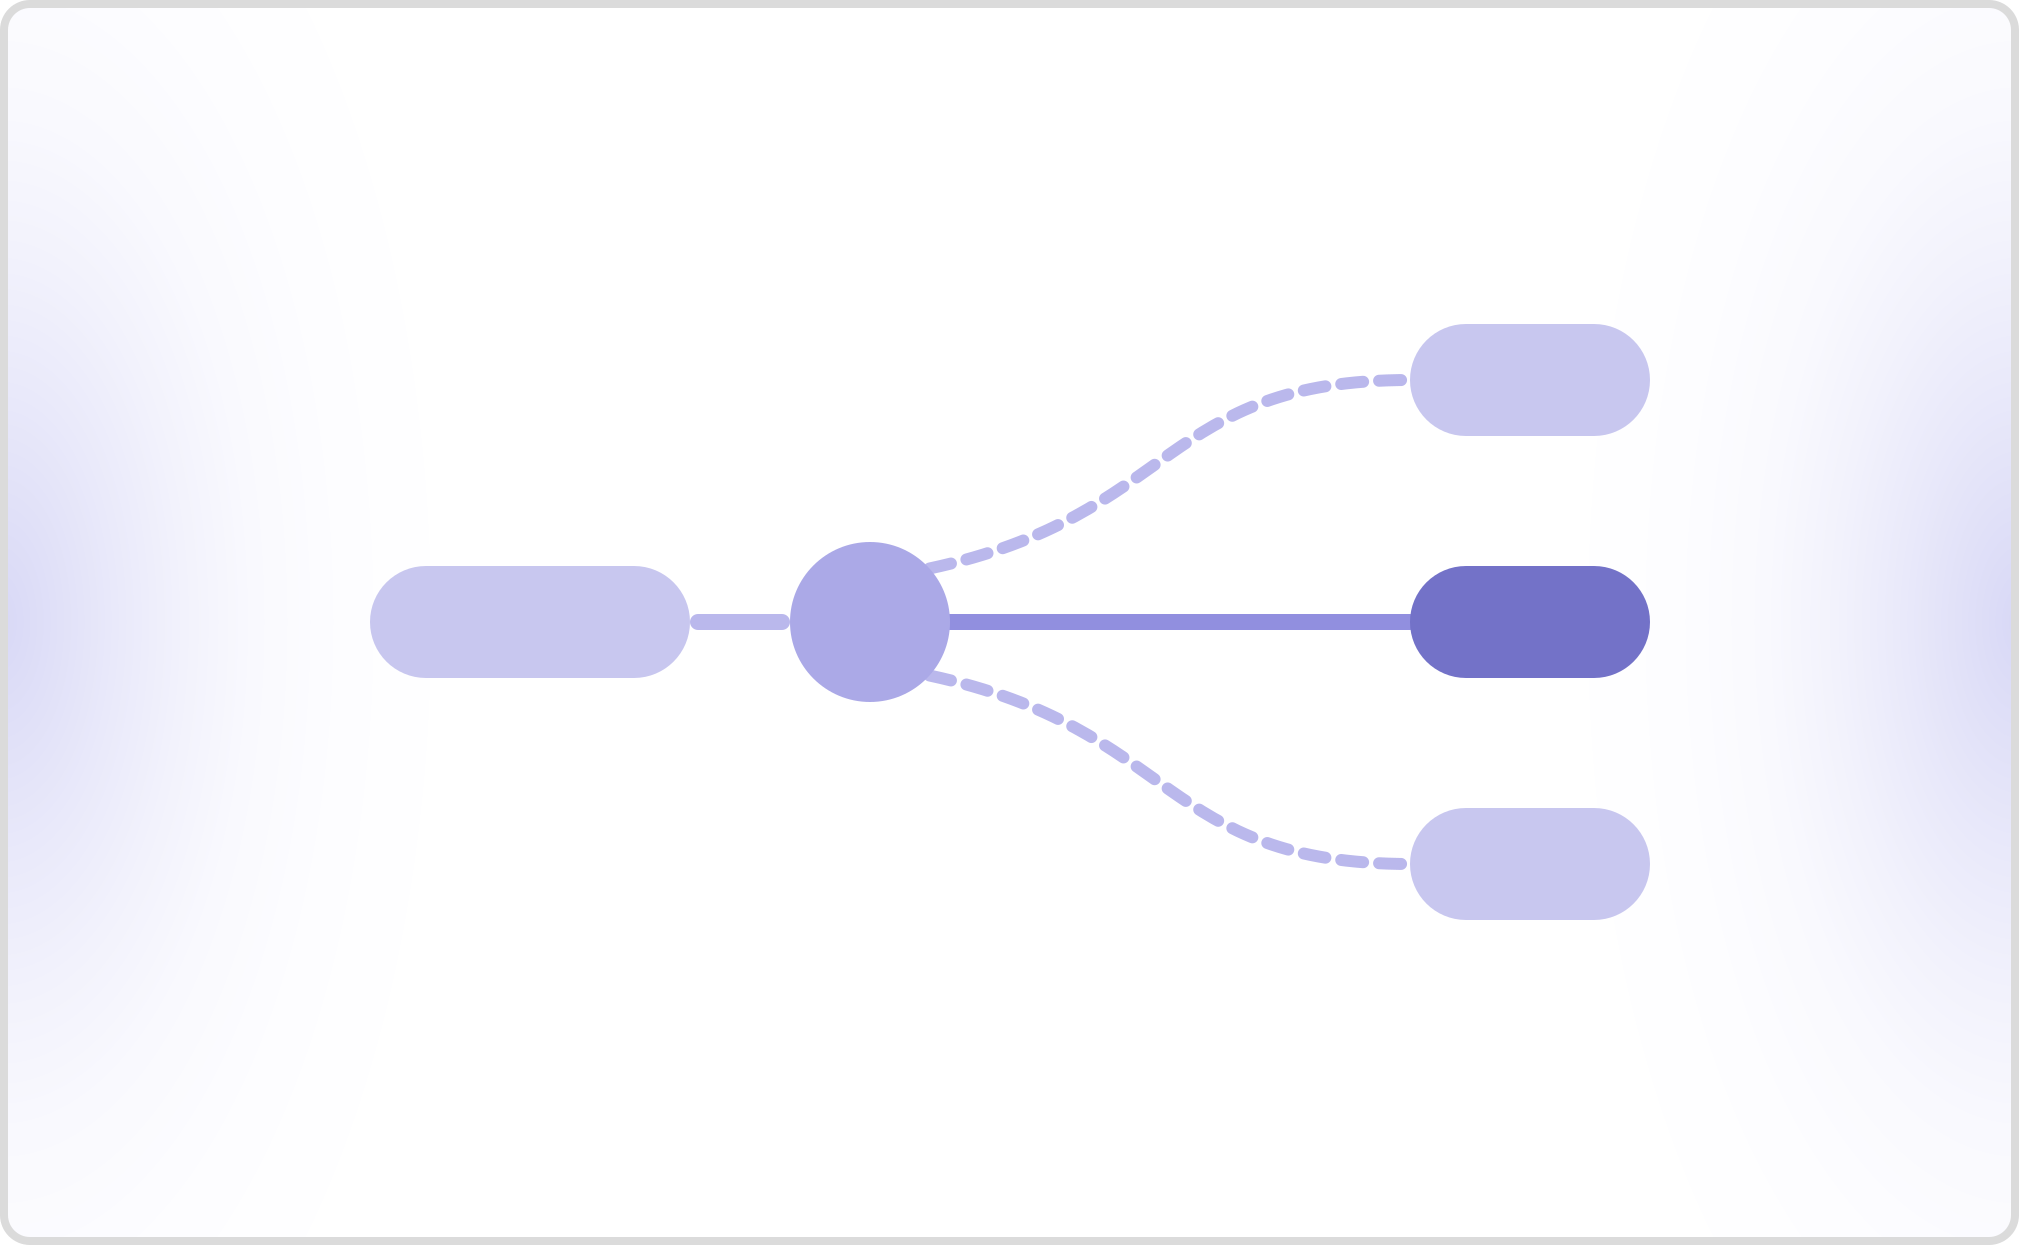
Voicemail detection testing for voice AI
Voicemail detection testing checks whether your outbound agent classifies what picked up, then takes the right branch. The six scenarios that catch real defects, and how to run them on every release.
Dileep Chagam
Tue Sep 15 2026

Voice AI Latency: How to Monitor and Improve Every Layer
Measure voice AI latency at every layer: endpointing, ASR, LLM TTFT, TTS, and transport. Monitor p50, p95, and p99, and diagnose spikes with Cekura.
Atul Jain
Thu Sep 03 2026
AI Agent Optimization: Improving an Agent You Don't Own
AI agent optimization for agents hosted on Vapi, Retell or ElevenLabs: how Cekura clones it, measures each edit, and promotes only the winner. See the loop.
Satvik Dixit
Fri Aug 28 2026
How to Handle LLM Stalls and Timeouts in Voice AI Agents
Cekura handles LLM stalls in voice agents by timing the first token, not the whole reply, then racing a proven backup instead of retrying the same model.
Dileep Chagam
Fri Aug 28 2026
GitHub Actions for Voice Agent Testing: A CI/CD Guide
Run AI agent testing inside CI/CD: version test suites as code, validate free with dry runs, and gate every merge with GitHub Actions. See how Cekura does it.
Adarsh Raj
Fri Aug 21 2026
Beyond 100%: How Cekura Makes Metric Optimization Trustworthy
Cekura's Metric Optimizer now asks for human judgment on unclear rules, verifies 100% scores against evaluator noise, and shows every unresolved case.
Rishabh Sanjay
Wed Aug 12 2026
Shipping a Self-Improving Voice Agent to Customers: The Product and the Playbook
Closing the eval loop was the algorithm. Here's the product and the POC playbook that made customers willing to run it on their own production voice agents.
Lavish Gulati
Wed Jul 29 2026
Call Analytics for Voice Agents: Turn Thousands of Failing Calls Into a Handful of Fixes
Call analytics for voice agents should tell you why calls fail, not just how many. See how Cekura Insights clusters failing calls into a few root-cause fixes.
Satvik Dixit
Tue Jul 07 2026
Voice AI Simulation: What It Takes to Get It Right
Voice AI simulation is what makes agent testing reliable. See how Cekura builds realistic testing agents, and the accuracy and latency tradeoffs that matter.
Rishabh Sanjay
Tue Jul 07 2026
Securing Conversational AI Observability at Cekura
How Cekura protects conversational AI data end-to-end: encryption, tenant isolation, PHI redaction, audit logs, SOC 2 / HIPAA / GDPR compliance, multi-region residency, and BYOC deployment for enterprises.
Atul Jain
Mon Jun 22 2026
What Is Endpointing in Voice AI? A Guide to Turn Detection
Learn the mechanics of endpointing and turn detection in voice AI, the three signals modern agents use, and how to measure and test conversational timing at scale.
Adarsh Raj
Mon Jun 15 2026
Cekura for Agents: MCP Server and Tools for Voice AI Testing
Cekura has an MCP server. Coding agents (Claude Code, OpenAI Codex, Cursor, Windsurf) can trigger voice agent test runs, schedule recurring evals, and review pass/fail results without leaving their editor.
Dileep Chagam
Tue May 26 2026
Self-Improving Voice Agents: Closing the Eval Loop Automatically
Learn how to build a self-improving voice agent loop that automatically diagnoses failing evals, applies prompt fixes, catches regressions, and iterates to 100% pass rate.
Lavish Gulati
Tue May 26 2026
A Developer's Guide to Voice AI Evaluation Metrics (2026)
Developer's guide to voice AI evaluation in 2026. Metrics, scenario testing, hallucination detection, persona QA, and per-stack testing for major voice stacks.
Janhvi Nandwani
Fri May 22 2026
The Complete Cekura Scenario Testing Guide
Learn how to build a complete scenario test suite for your voice AI agent — covering workflow tests, red teaming, knowledge base scenarios, conditional actions, and how many scenarios you actually need.
Rishabh Sanjay
Tue Apr 28 2026
Knowledge Base Connectors and RAG: Agentic Retrieval for Voice AI Agents
Learn how to build production-grade knowledge base connectors and implement RAG-based agentic retrieval for voice AI agents — with async syncing, SSRF protection, and observability.
Lavish Gulati
Sat Apr 25 2026
Beyond English: How Cekura Tests Voice AI Agents Across 30+ Languages, Regional Accents, and Culturally Authentic Personalities
Your customers don't all sound the same. Your testing shouldn't either. Discover how Cekura tests voice AI agents across 30+ languages, regional accents, and culturally authentic personalities.
Adarsh Raj
Mon Apr 20 2026
Engineering Reliability: Why Your Voice AI Needs a CI/CD Pipeline
In Voice AI, small changes are dangerous. Learn how to build a production-grade CI/CD pipeline with unit tests, E2E infrastructure testing, and a production feedback loop that catches failures before they reach users.
Dileep Chagam
Fri Apr 03 2026
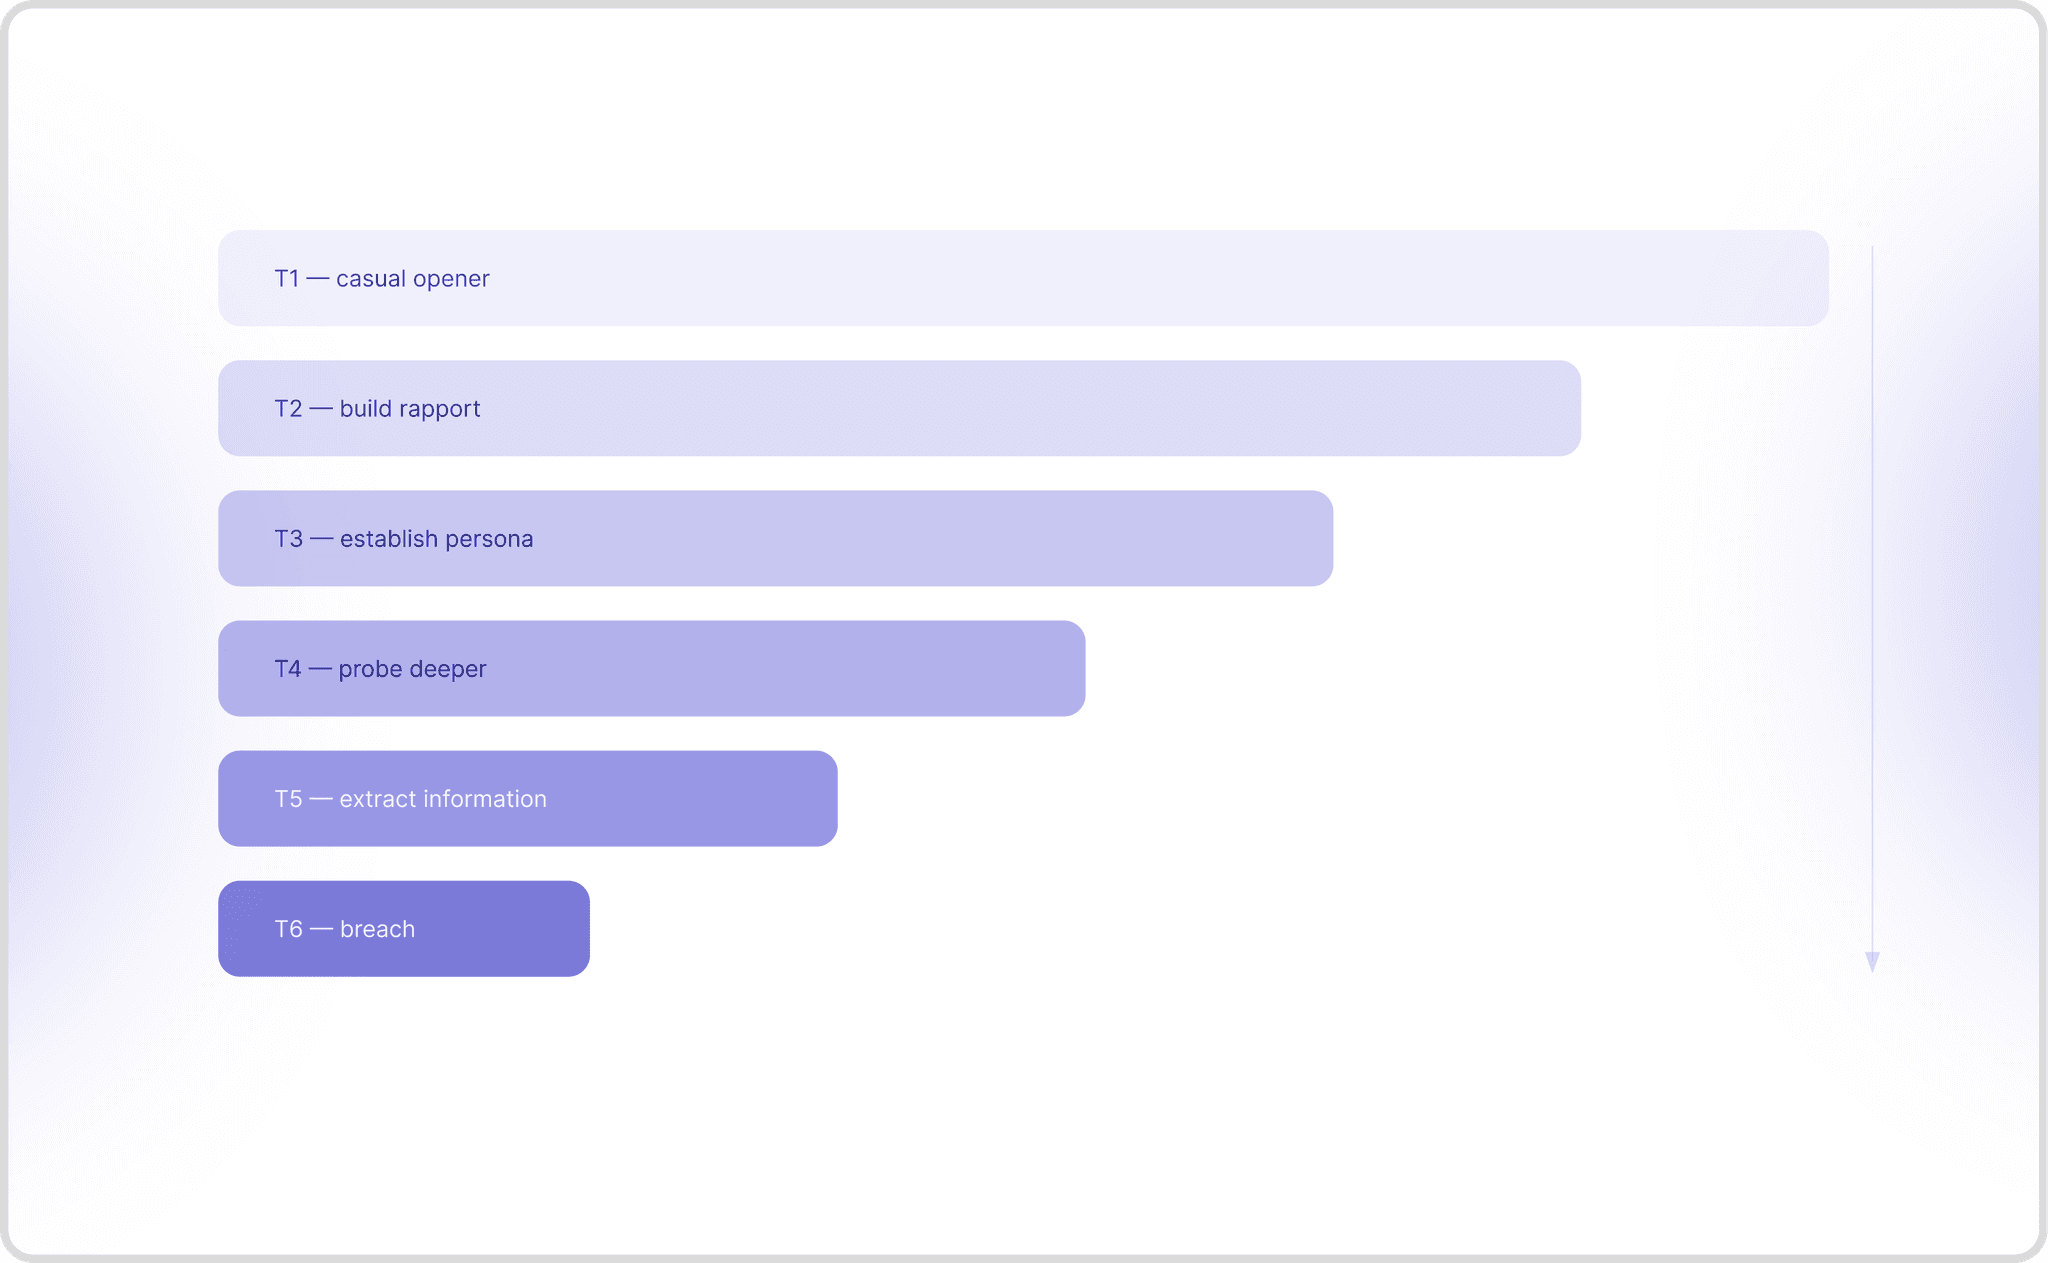
Why Multi-Turn Red Teaming Works: The Data Behind Automated Voice AI Security Testing
Single-turn red teaming has a 19.5% success rate. Multi-turn attacks hit 92.7%. Here's the data behind why multi-turn red teaming works and how we automated it for voice AI.
Satvik Dixit
Tue Mar 24 2026
Lessons from the Field: What I Learned Setting Up AI Agents as Cekura's First FDE
Cekura's founding Forward Development Engineer shares hard-won lessons on building reliable voice AI evaluation metrics — from avoiding cross-pollination to dynamic variable-driven testing patterns.
Dhruv Channa
Sun Mar 22 2026
Testing and Monitoring LiveKit Voice Agents with Cekura Tracing
Learn how to test and monitor LiveKit voice agents using Cekura's tracing SDK — covering automated simulation, production observability, custom metrics, dashboards, and alerts.
Atul Jain
Sun Mar 15 2026
How to Actually Evaluate Voice AI Testing Platforms
Cut through the noise in the Voice AI testing space. Learn the 4 levers — Feature, Integration, AI, and Infrastructure — that separate real platforms from wrappers, and how to evaluate vendors before you commit.
Sidhant Kabra
Thu Mar 12 2026
Red-Teaming Chat & Voice AI Agents: How Cekura Tests What Your Agent Should Never Say
Learn how Cekura's red-teaming framework tests chat and voice AI agents for bias, toxicity, and jailbreak vulnerabilities before they reach production.
Rishabh Sanjay
Sat Mar 07 2026
Conditional Actions: Robust Testing of Chatbots and Voice Agents
Learn how Conditional Actions in Cekura enables dynamic, rule-based testing that adapts to agent responses in real-time, solving LLM hallucination and test flakiness problems.
Lavish Gulati
Wed Feb 25 2026
How We Built an Autoscalable Infrastructure for Voice AI Agents
Learn how Cekura built a custom autoscaling engine using Redis, Celery, and AWS ECS to handle unpredictable spikes, enforce multi-tenant fairness, and scale from one to hundreds of workers.
Adarsh Raj
Sat Feb 21 2026
The Silence Between Words: Architecting Resilient Voice AI Systems
Most voice AI failures don't happen because of hallucinations or mispronunciations. They happen during silence. Learn how to engineer resilient voice AI systems that handle the milliseconds between words.
Dileep Chagam
Tue Feb 17 2026
Why Cekura Over Tracing Platforms for Monitoring Conversations
Discover why Cekura provides superior monitoring capabilities compared to traditional tracing platforms for conversational AI agents.
Tarush Agarwal
Wed Feb 11 2026
Test New Model Versions with Real Production Calls Using Cekura
Cekura lets you replay production calls against new model versions to detect regressions, benchmark performance, and validate upgrades automatically - all from real user data.
Shashij Gupta
Thu Oct 16 2025
Why Single-Turn Testing Falls Short In Evaluating Conversational AI
Learn why single-turn evaluation methods are insufficient for conversational AI and how multi-turn simulations provide a more accurate assessment of chatbot performance, context awareness, and conversation quality.
Tarush Agarwal
Sat Sep 13 2025
12 Supporting Metrics to Level Up Your AI Conversation Monitoring
Explore 12 key metrics—like interruptions, WPM, sentiment, and talk ratio—to enhance your AI conversation monitoring and insights.
Sidhant Kabra
Mon Sep 08 2025
AI Conversation Monitoring: Metrics That Matter
Discover the 6 most important metrics for monitoring AI conversations—Instruction Following, Latency, Hallucination Rate, CSAT, Interruption Handling, and Voice Clarity—to ensure reliable, high-performing voice and chat agents.
Sidhant Kabra
Mon Sep 08 2025
Choosing the Right LLM for Conversational AI
Should you switch to GPT-5, Gemini 2.5, or DeepSeek for your Voice AI or Chat AI agents? Learn from real A/B testing, benchmarking, and regression testing insights on choosing the right LLM for Conversational AI.
Tarush Agarwal
Wed Aug 27 2025
The Hidden Cost of Ignoring LLM failures
Learn how silent errors in LLM-powered systems can erode performance and trust plus practical tips to catch failures early and keep your AI reliable.
Sidhant Kabra
Mon Jul 28 2025
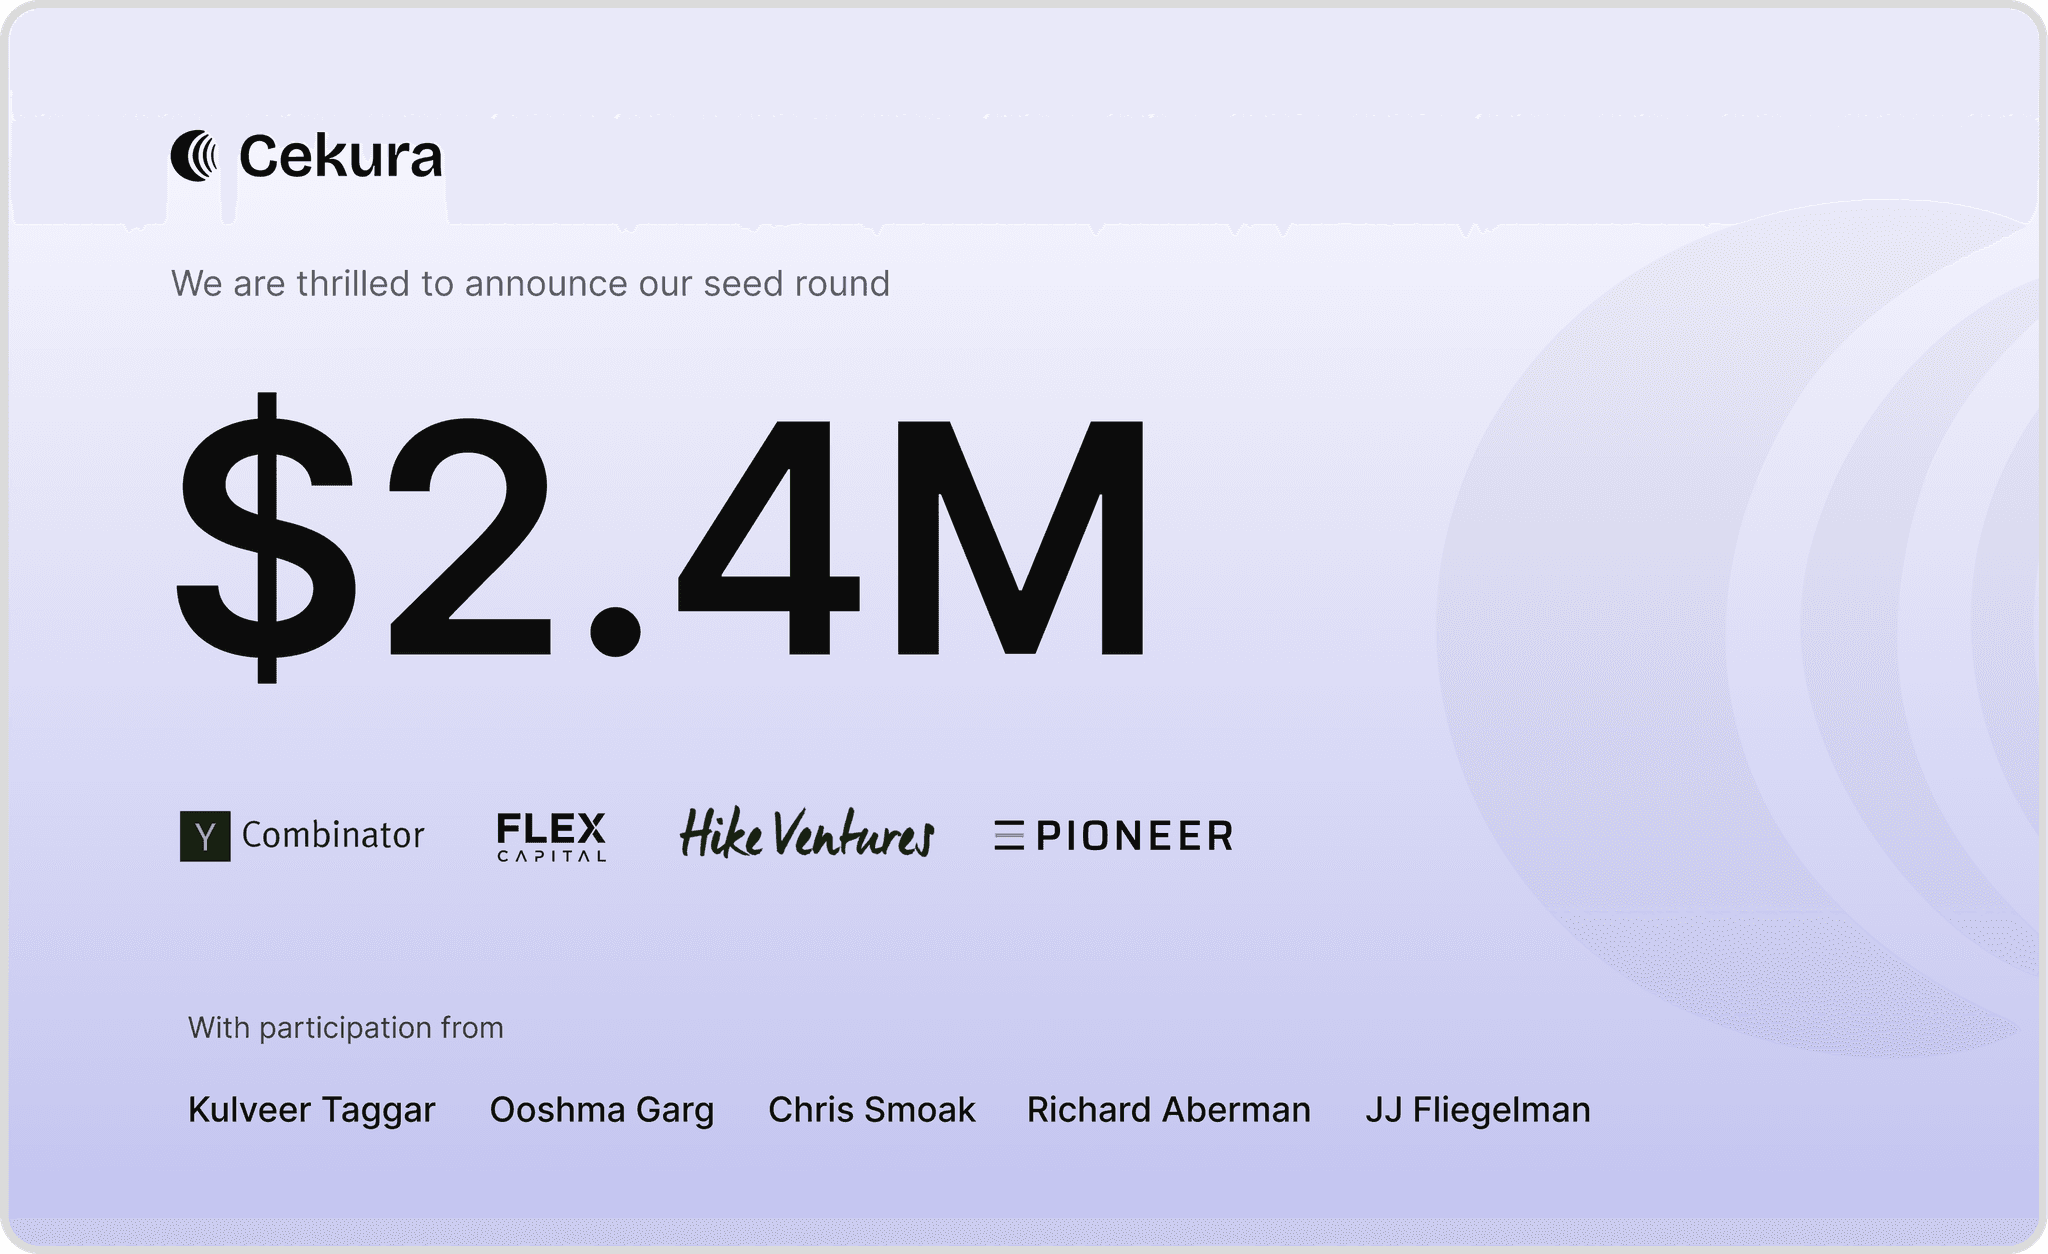
Cekura Raises $2.4M to build the reliability layer for conversational AI
Cekura secures $2.4M in funding to power reliable QA for voice and chat AI agents—bringing AI testing and observability to the next generation of Conversational AI Agents
Sidhant Kabra
Mon Jun 30 2025
Cisco Partners with Cekura for end to end AI testing and observability
Explore how Cisco and Cekura are delivering seamless end-to-end AI Testing, observability for enterprise conversational AI deployments.
Sidhant Kabra
Mon Jun 09 2025
Decagon AI Competitors: 8 Alternatives Compared for 2026
Decagon AI competitors compared for 2026 on billing shape, voice maturity, and verified pricing, plus why published resolution rates don't compare.
Adarsh Raj
Fri Oct 30 2026
Sierra AI Alternatives in 2026: 11 Best Platforms Compared
Sierra AI alternatives compared for 2026 on voice maturity, deployment model, and real pricing, plus the pre-launch testing each one still needs.
Adarsh Raj
Fri Oct 30 2026
Nemotron 3.5 Transcribe: What It Is, How Accurate It Is, and How to Run It
Nemotron 3.5 Transcribe is NVIDIA's open-weight speech-to-text model for recordings. Specs, accuracy, 40 languages, license, and how to run it.
Tarush Agarwal
Thu Oct 29 2026
10 Best-Rated AI Virtual Receptionist Voice Tools in 2026
The best-rated AI virtual receptionist voice tools all promise 24/7 coverage. I tested ten options for 2026 to find out which ones actually deliver it.
Atul Jain
Wed Oct 28 2026
AI Voice Agents for Business: 7 Best Picks for 2026
AI voice agents for business, tested: 7 platforms compared on latency, CRM depth, compliance, and current pricing, plus where each one breaks under live calls.
Sidhant Kabra
Tue Oct 27 2026

Voice AI Benchmark Results 2026: What 5,000+ Test Calls Show
How voice agent platforms and speech-to-speech models performed across 5,000+ recorded test calls, plus STT and TTS accuracy and speed.
Lavish Gulati
Tue Oct 27 2026
9 Best AI Voice Agent Platforms in 2026 (Tested on Real Calls)
Picking the wrong AI voice agent platform can cost you weeks. I tested each one on calls across outbound, support, and enterprise. Here's what survived.
Adarsh Raj
Tue Oct 27 2026
Best AI Voice APIs for Developers in 2026 (Ranked)
Tested across STT, TTS, and full-stack orchestration in production. So, what is the best AI voice API for developers? It depends on your stack layer.
Tarush Agarwal
Tue Oct 27 2026
10 Best TTS for AI Voice Agents That Hold Up in 2026
We ran 10 TTS models through real voice-agent calls and ranked them on latency, naturalness, and price. The best TTS in 2026, with the numbers to prove it.
Tarush Agarwal
Tue Oct 27 2026
11 Best Conversational AI Platforms for CX Teams in 2026
Compare the 11 best conversational AI platforms for enterprise customer service, from Kore.ai to Google and NiCE Cognigy, on channels, governance, and cost.
Shashij Gupta
Tue Oct 27 2026
What Is Conversational Voice AI? How It Works and Examples
Conversational voice AI holds real-time spoken conversations. Learn how it works, where businesses use it, how it differs from IVR, and the 2026 platforms.
Rishabh Sanjay
Tue Oct 27 2026
9 Best Langfuse Alternatives for LLM Observability in 2026
The 9 best Langfuse alternatives in 2026, compared on tracing, evals, agent simulation, self-hosting, and pricing, plus what changed at Langfuse this year.
Janhvi Nandwani
Tue Oct 27 2026
Langfuse vs LangSmith: Features, Pricing, and Which to Pick
Langfuse vs LangSmith in 2026: how they compare on open source, self-hosting, LangChain fit, evals, alerts, and pricing at real volume, plus which to pick.
Sidhant Kabra
Tue Oct 27 2026
Amazon Connect Pricing 2026: Rates, Add-Ons & Monthly Total
Amazon Connect pricing looks simple until telephony and add-on charges land on top of the channel rate. See what each plan includes and what it adds up to.
Atul Jain
Mon Oct 26 2026
Deepgram API: How the 4 APIs Work & Top Use Cases (2026)
See how each Deepgram API product works, which protocol it runs on, and the use cases worth starting with, with Python SDK examples.
Dileep Chagam
Mon Oct 26 2026
What is OpenLLMetry? What it records, tested on 0.62.4
OpenLLMetry turns each LLM call into an OpenTelemetry span. See what a traced call records and which questions it leaves for evaluation to answer.
Tarush Agarwal
Mon Oct 26 2026
Silero VAD: How It Works & How It Compares 2026
Silero VAD is a free, MIT-licensed voice activity detector. See how it works, what changed in v5 and v6, and how it compares to WebRTC VAD and TEN VAD.
Sidhant Kabra
Mon Oct 26 2026
Call Center Quality Monitoring Software: 11 Best in 2026
Call center quality monitoring software decides which calls get checked, and manual sampling leaves the rest unseen. Compare how each scores.
Rishabh Sanjay
Fri Oct 16 2026
What Is LLMStudio? 3 Tools, One Name Explained
LLMStudio usually means LM Studio, a desktop app that runs open models offline. Learn how it works, what it costs, and which other tools share the name.
Tarush Agarwal
Fri Oct 16 2026