A voice agent can nail a single sentence and still fall apart the moment a real back-and-forth starts. Conversational voice AI is the layer that has to hold that back-and-forth in real time, and it breaks in places single-utterance demos never show.
We test these agents for a living at Cekura, so this guide covers what conversational voice AI is, how the real-time loop works, where businesses use it, and the platforms that matter in 2026.
What Is Conversational Voice AI?
Conversational voice AI is software that holds a spoken, back-and-forth conversation with a person in real time. It listens while you talk, works out when you are done, decides what to say, and speaks back fast enough to feel natural. That last part is the hard part.
It gets confused with a few simple things. Text-to-speech reads text aloud and stops. A voice command handles one request, then waits. An IVR plays a fixed menu and listens for a keypress.
Voice-based conversational AI runs many turns, carries context across them, and adapts when the caller changes direction mid-call.
If you swap the keypress for speech, you get conversational IVR, which has its own page covering how it differs from touch-tone and which metrics matter.
How Conversational Voice AI Works: The Real-Time Conversation Loop
Conversational voice AI works as a loop that has to close in under a second, every single turn.
Under the hood, it still moves audio through speech recognition, a language model, and speech synthesis, which we break down layer by layer in our guide to how AI voice assistants process human language.
This section is about the part those breakdowns skip: the timing, and how the loop decides when to listen, when to talk, and when to stop.
The Latency Budget Every Turn Has to Hit
Every spoken turn has a latency budget, and it is shorter than most people expect.
A 2009 study in PNAS measured this across ten languages and found that people tend to avoid overlap and keep the gap short, usually within about 200 ms.
People hit that window because they don't wait for silence to start their turn. They use grammar, rhythm, and context to predict when the other person will finish, and plan their reply while that person is still talking.
An agent that waits for silence, then starts thinking, then starts speaking, is already behind.
That budget has to cover everything, which means detecting that you stopped, running the model, generating audio, and pushing it down the line. If you miss it, the pause reads as awkward.
Turn-Taking and Endpointing
Turn-taking is the agent's guess about when you are actually done speaking, which is called endpointing. When you get it wrong in one direction, the agent talks over you. Get it wrong in the other, and it sits in silence while you wait.
Voice activity detection (VAD) listens for the end of speech. A pause isn't always a finished thought, though. People stop to breathe, to think, mid-sentence.
This is where tuning matters. Google’s Live API docs call a 500 to 800 ms silence window a good balance before the agent assumes you are finished, and the server defaults to about 800 ms.
Interruptions and Barge-In
Barge-in lets a caller cut the agent off mid-sentence and be heard. Real conversations are full of this. You answer before the other person finishes, or you correct yourself halfway through.
A natural agent has to stop talking the instant you start, drop the half-spoken line, and listen. This is harder than it sounds, because the agent is producing audio and receiving it at the same time.
Most production stacks handle it with fast detection and cancellation, but the newer approach builds it into the model itself, which is where the architecture is heading.
Cascaded Pipelines vs. Speech-to-Speech Models
Two architectures run conversational voice AI today. The older one is cascaded, and the newer one is speech-to-speech.
A cascaded pipeline chains three models. Speech-to-text writes down what you said, a language model decides the reply, and text-to-speech voices it. You can swap any piece independently. You also pay a latency tax at every handoff, and tone and emotion flatten out when speech becomes plain text.
A speech-to-speech model skips the text round trip. It takes audio in and puts audio out through a single model, so prosody, pace, and emotion survive the trip.
OpenAI made its Realtime API generally available with gpt-realtime in August 2025, and Amazon's Nova 2 Sonic and Google's Gemini Live API work the same way.
Speech-to-speech is faster and more expressive. It also gives you less control over each step and is newer in production. Plenty of live agents still run cascaded for exactly that reason.
What Makes Voice AI Feel Conversational
Voice AI feels conversational when it handles timing, emotion, memory, and personality the way a person would. The audio itself is rarely the problem anymore.
Sesame, a conversational speech lab, ran a listening study comparing AI speech to human recordings. With no context, listeners showed no clear preference between the AI and the real recordings.
Audio realism is close to a solved problem. Add some conversation context, though, and listeners consistently preferred the human recordings.
The conversation around the voice is what still gives the agent away. Sesame frames the missing piece as voice presence, built from emotional read, conversational timing, context awareness, and a steady personality.
A reply has to fit the moment as well as the words, which is why voice choice and prosody carry so much weight. The same sentence can sound warm, bored, or rushed depending on delivery.
Conversational Voice AI Examples and Use Cases
Conversational voice AI already runs real workloads, mostly on the phone. Here's where it shows up most, with numbers the companies themselves published.
Customer Support
Support lines were the first big use case, because so many calls repeat the same handful of questions. Revolut uses ElevenLabs Agents for customer support and reports the agents resolve tickets in under 5 minutes, while tickets used to take 8x as long or more.
Appointment Booking and Reminders
Scheduling calls are short, structured, and constant, which makes them a natural fit.
Pine Park Health's voice agent on Retell calls patients two days before each visit, verifies identity, confirms or reschedules, and writes the result into the medical chart. A second outbound agent books 55.7% of the patients it reaches..
Billing and Collections
Billing calls need the agent to look up an account and take action mid-call. Medical Data Systems handles about 30,000 calls a month with voice agents on Retell, answers 100% of inbound calls with a 30% transfer rate, and collects around $280,000 a month with them.
Consumer Voice Assistants
On the consumer side, ChatGPT Voice lets you talk with ChatGPT hands-free and interrupt it anytime, and its newest Live mode can listen and speak at the same time. Gemini Live does the same inside the Gemini app, where you can interrupt or change the subject mid-conversation.
Conversational Voice AI vs. Voice Assistants, IVR, and Chatbots
The line that separates them is whether the system holds a real conversation or just reacts to one input, and whether it does it in speech.
| Type | Turns | Carries context? | Example |
|---|---|---|---|
| Conversational voice AI | Many, real-time | Yes | Phone agent that books, reschedules, and answers follow-ups |
| Chatbot | Many, typed | Usually | Website chat that answers order questions |
| Voice assistant | One request at a time | Limited | "Set a timer for 10 minutes" |
| IVR phone tree | Fixed menu | No | "Press 1 for billing" |
| Text-to-speech | None | No | Reading an article aloud |
The underlying speech recognition, reasoning, and speech synthesis are shared plumbing. The difference is how much of a conversation each one can hold, and how fast it has to respond.
Conversational Voice AI Platforms in 2026
The platforms behind conversational voice AI fall into three groups, and most teams combine at least two:
-
Speech-to-speech models (generate the conversation): OpenAI's realtime models (GPT-Live 1 and GPT-Realtime-2.1), Google’s Gemini Live API on Gemini 3.8 Live, now its default Live model, and Amazon Nova 2 Sonic on Bedrock.
-
Full-stack voice agent platforms (wrap models with tools, telephony, and dashboards): ElevenAgents from ElevenLabs, which supports 90+ languages and reports more than 7 million agents launched, plus VAPI, Retell, and Bland.
-
Real-time frameworks (move the audio and handle turn detection): LiveKit, open-source WebRTC infrastructure you can self-host end-to-end, and Pipecat, an open-source Python framework for real-time voice agents.
Before committing to a speech-to-speech model, check the model comparison on Cekura's benchmarks.
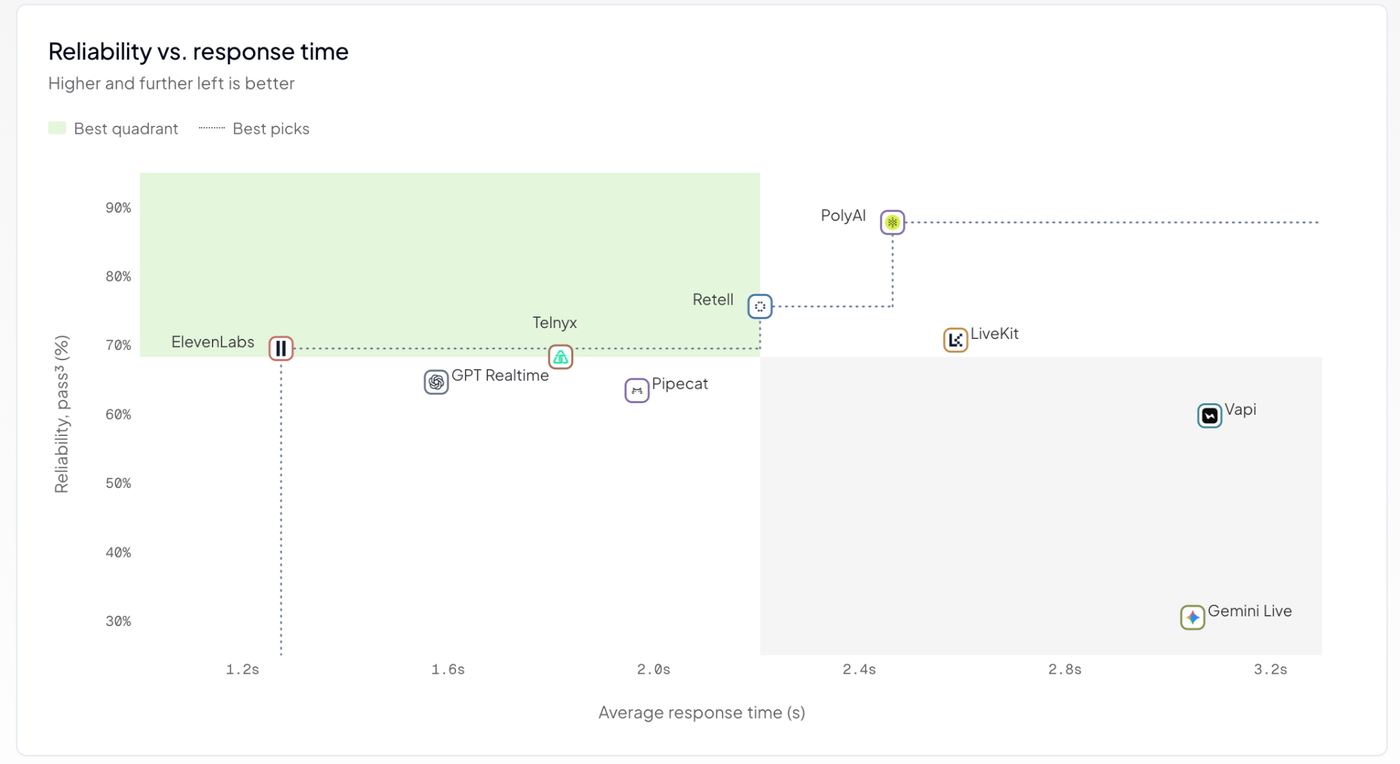
Reliability vs. response time across 3,198 live calls. Source: Cekura speech-to-speech benchmark, October 2026.
Best Practices for Building Conversational Voice AI
A handful of practices decide whether your agent holds a conversation or just survives one. Each one targets a place where real calls break.
Budget your latency end to end. Set a target for total response time and measure it on real telephony, since localhost hides most of the delay. Every provider swap changes the number. Track time-to-first-audio per turn, because that is the delay a caller actually feels.
Tune endpointing for your callers. A silence window that suits crisp speakers cuts off people who pause to think. Test with slow talkers, strong accents, and noisy lines, then set the window to fit them.
Design barge-in on purpose. Decide exactly what the agent does the instant a caller speaks over it. Stop, drop the half-spoken line, and listen. An agent that talks through interruptions feels deaf to the person on the line.
Test full conversations, turn by turn. A scripted reply can pass a one-line check and still collapse over a five-turn call. Single-turn evals miss the context, memory, and recovery that real conversations demand.
Watch conversation-level metrics. Total calls handled tells you little on its own. Interruption counts, latency, sentiment, and completion rate tell you whether the conversation worked, so track voice AI evaluation metrics per scenario, where a failing flow can't hide inside a blended average.
How to Test and Monitor Conversational Voice AI with Cekura
A confused caller or a missed interruption only shows up across thousands of calls, long after launch, and by then real customers have already hit it.
Cekura runs the calls you can't run by hand and watches the ones already happening, across pre-production, infrastructure, and live calls.
With Cekura, teams can:
-
Simulate thousands of multi-turn conversations before go-live, including off-script callers and adversarial inputs.
-
Red-team the agent automatically, so a real customer never finds the edge case first.
-
Test infrastructure behavior like interruptions, background noise, latency, and voice activity detection under real call conditions.
-
Score every live call on latency, interruptions, sentiment, and instruction following, with alerts the moment something slips.
-
Plug into the stack you already run, with native integrations for Retell, VAPI, ElevenLabs, LiveKit, Pipecat, and Bland.
-
It’s SOC 2-, HIPAA-, and GDPR-compliant for transcript redaction, role-based access, and audit trails.
The major labs are already moving conversation into the model itself, with systems that listen and speak at once, and the agents that win will be the ones tested on the messy middle of a real conversation.
Book a demo to see how Cekura tests your conversational voice AI before your callers find the cracks.
Frequently Asked Questions
What are examples of conversational voice AI?
Examples of conversational voice AI include phone agents that handle customer support, appointment booking, and billing, plus consumer assistants like ChatGPT Voice and Gemini Live. Revolut, Pine Park Health, and Medical Data Systems all run voice agents on real customer calls.
Is there a free conversational voice AI app?
Yes, ChatGPT Voice and Gemini Live both have free tiers. ChatGPT gives free users limited access to voice, with longer daily limits on paid plans, and Gemini Live is available in the free Gemini app on Android and iOS, with some features requiring a subscription.
How is conversational voice AI different from a chatbot?
The main difference between conversational voice AI and a chatbot is the channel and the timing. A chatbot trades text with no real-time pressure. Conversational voice AI works in spoken audio, where a pause longer than about a second already feels wrong.
What is the difference between conversational AI and voice AI?
The main difference between conversational AI and voice AI is scope. Conversational AI covers both voice and chat. Voice AI is the audio side specifically, where speech recognition, turn-taking, and speech synthesis come into play.
How does conversational voice AI handle interruptions?
Conversational voice AI handles interruptions with barge-in. The system detects that the caller has started speaking, stops its own audio immediately, and listens, then plans a fresh response from what it heard.
Is conversational voice AI the same as a voice assistant?
No, conversational voice AI goes further than a typical voice assistant. A voice assistant usually handles one request at a time, while conversational voice AI carries context across a full multi-turn conversation and recovers when the topic shifts.