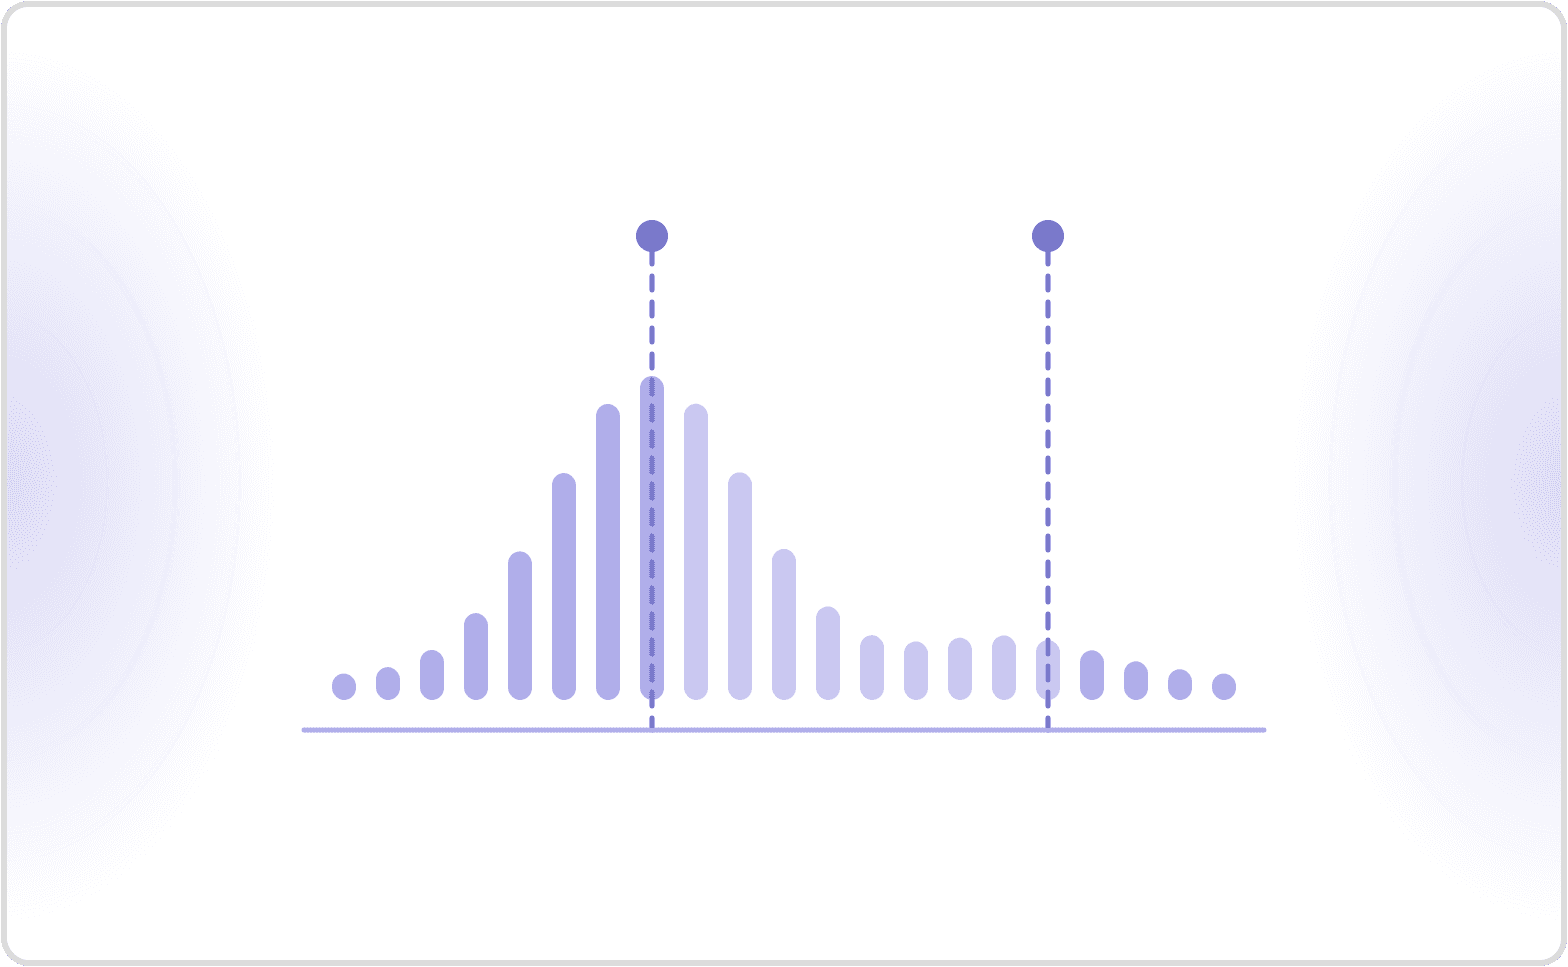
What is P50? P50 is the 50th percentile, or median: half of all measurements are at or below it. P90 is the value 90% of measurements stay at or below, and P95 the value 95% stay at or below. In latency, P50 describes the typical response and P90 or P95 describe the slow tail.
TL;DR: P50, P90 and P95
- P50 is the median. P90 and P95 are the values that 90% and 95% of measurements stay at or below, so 1 in 10 and 1 in 20 measurements are slower.
- In latency, a higher P90 is worse. In oil, gas and solar forecasts, P90 is the conservative low estimate that the outcome equals or beats 90% of the time.
- On 20 illustrative voice agent turns, three standard formulas put P90 at 2,100, 2,280 or 3,720 ms. On small samples the method matters, so report it with N.
- The mean of those 20 turns is 1,585 ms, yet 16 of the 20 turns were faster than that. One slow turn drags the mean and leaves the middle value alone.
- Tail percentiles need volume. At 20 measurements only two values sit above P90, so one slow turn can move it. As a rule of thumb, wait for about 100 measurements before trusting it and 200 before trusting P95.
What is P50?
P50 is the 50th percentile of a data set, the value that splits it in half. Half of the measurements are at or below it and half are at or above it. Statisticians call the same number the median.
The “P” stands for percentile, and the number after it tells you what share of measurements sit at or below the value. The NIST Engineering Statistics Handbook defines the pth percentile as a value that at most p% of measurements fall below. P50, the 50th percentile and the median are three names for one number.
In latency monitoring, P50 answers one question: how long does a typical request take? If your API’s P50 is 120 ms, half of requests finish in 120 ms or less. For a voice agent with a 1.6 s P50, the typical caller hears 1.6 s of silence after they stop talking.
The number says nothing about the slow half. A system can look healthy in the middle while 1 in 10 responses takes three times as long. That is why it almost always appears next to P90, P95 or P99.
Not every P50 is a percentile of response times. In physiology it is shorthand for how tightly hemoglobin binds oxygen, in neuroscience it names an auditory brain response that peaks about 40 to 75 ms after a sound, and in skincare it is the name of a lotion. P90 has its own detours: a compact submachine gun and a guitar pickup. This guide covers the statistic.
What is P90, and what does P90 mean?
P90 means the 90th percentile: 90% of measurements are at or below this value and 10% are above it. If your P90 latency is 2.2 s, nine in ten responses arrive within 2.2 s and one in ten takes longer.
P90 explained in one line: it marks where the slowest tenth of responses begins. It sits far enough into the tail to catch problems the median hides. It also rests on a tenth of your data, so it settles down at moderate volumes where P99 still jumps around.
Because P90 describes the slowest 10%, it moves when something hits a minority of requests. Think of a slow database query on one code path, a cold start after an idle period, or a tool call that only some conversations trigger. The typical response would not change in any of those cases.
What is P95, and how does it differ from P99?
P95 is the 95th percentile: 1 in 20 measurements is slower. It makes a good first alerting threshold, because it reaches further into the tail than P90 while needing far less data than P99.
P99 is the 99th percentile: 1 in 100 measurements is slower. It shows a plausible worst case, but it needs high volume to be stable. For P99 in voice agents, including what causes tail spikes and how to reduce them, read what P99 latency means for voice AI agents.
Percentile cheat sheet: P25 to P99
Each percentile answers a different question about the same data. The last column shows why the high percentiles need more data.
| Label | Also called | Share at or below | Share slower | What it tells you in latency | Values above it at N = 1,000 |
|---|---|---|---|---|---|
| P25 | First quartile | 25% | 75% | The fast end of normal | 750 |
| P50 | Median | 50% | 50% | The typical request or turn | 500 |
| P75 | Third quartile | 75% | 25% | The upper edge of normal; P25 to P75 is the interquartile range | 250 |
| P90 | 90th percentile | 90% | 10% | Where the slowest 10% begins | 100 |
| P95 | 95th percentile | 95% | 5% | A first alerting threshold | 50 |
| P99 | 99th percentile | 99% | 1% | A plausible worst case | 10 |
Read the table from the bottom up when you debug. If only P99 moves, a rare event changed. If P90 moves and P50 does not, a slow path got slower or more common. If P50 moves, something changed for everyone.
P90 meaning in latency vs energy and reserves forecasts
P90 means opposite things in different fields, and search results for “P90 meaning” mix both. In latency and web performance, it is the 90th percentile, a high value, and a higher one is worse. In oil and gas reserves and solar energy yield estimates, P90 is an exceedance value: the estimate the real outcome equals or beats 90% of the time.
The U.S. SEC rule for oil and gas reporting, 17 CFR 210.4-10, sets this convention for reserves. Under it, proved reserves must meet a reasonable-certainty test, which with probabilistic methods means at least a 90% probability that recovered quantities equal or exceed the estimate. For the proved plus probable estimate the same rule sets at least a 50% probability, and for proved plus probable plus possible at least 10%.
Solar data provider Solargis defines P90 the same way: the energy output expected to be exceeded in 90% of cases. In exceedance terms, P90 is the 10th percentile of the outcome distribution. It is the low, conservative estimate, and P10 is the optimistic high case.
P50 is the median in both conventions. Project cost and schedule risk analysis follows the percentile convention: a P90 finish date is one that 90% of simulated outcomes meet or beat, so it sits later than P50 and is the cautious choice.
| Latency and performance monitoring | Reserves and energy yield forecasts | |
|---|---|---|
| What P90 means | 90% of measurements are at or below it | 90% probability the outcome equals or exceeds it |
| Equivalent percentile | 90th | 10th |
| Position relative to the median | Above it | Below it |
| A higher P90 is | Worse (a slower tail) | Better (a larger conservative estimate) |
To tell which one a report uses, check whether its P90 sits below or above its P50. Below means the exceedance convention. Above means the percentile convention that the rest of this guide follows.
How to calculate P50, P90 and P95 (worked example)
To calculate a percentile, sort the measurements from fastest to slowest and find the value at the matching rank. The simplest version is the nearest-rank method: rank = ceil(p × N), where p is the percentile as a fraction and N is the number of measurements. “Ceil” means round up to the next whole number.
Here are 20 illustrative response times, in milliseconds, from turns in a voice agent’s calls:
820, 870, 910, 940, 980, 1,010, 1,040, 1,080, 1,100, 1,150, 1,180, 1,220, 1,260, 1,310, 1,380, 1,450, 1,600, 2,100, 3,900, 6,400
- Sort the values from fastest to slowest. The list above is already sorted.
- Find P50. The rank is ceil(0.50 × 20) = 10, and the 10th value is 1,150 ms.
- Find P90. The rank is ceil(0.90 × 20) = 18, and the 18th value is 2,100 ms.
- Find P95. The rank is ceil(0.95 × 20) = 19, and the 19th value is 3,900 ms.
- Write N next to every result. Here P90 rests on the two slowest turns and P95 on one.
Calculate P50, P90 and P95 in Python
The same three results take a few lines of Python. The nearest-rank function matches the hand calculation, and NumPy’s default shows the interpolated answer.
import math
import numpy as np

turns_ms = [820, 870, 910, 940, 980, 1010, 1040, 1080, 1100, 1150,
            1180, 1220, 1260, 1310, 1380, 1450, 1600, 2100, 3900, 6400]

def nearest_rank(values, p):
    ordered = sorted(values)
    return ordered[math.ceil(p / 100 * len(ordered)) - 1]

for p in (50, 90, 95):
    print(p, nearest_rank(turns_ms, p), round(np.percentile(turns_ms, p)))
Output:
50 1150 1165
90 2100 2280
95 3900 4025
Same data, three different answers
Nearest rank is only one of several standard definitions. NumPy’s percentile function offers 13 methods, nine of them from Hyndman and Fan’s 1996 survey of statistical packages, and defaults to linear interpolation. The NIST handbook uses another, based on p × (N + 1). Run all three on the 20 turns above and you get:
| Method | P50 | P90 | P95 |
|---|---|---|---|
| Nearest rank (NumPy “inverted_cdf”) | 1,150 ms | 2,100 ms | 3,900 ms |
| Linear interpolation (NumPy default, “linear”) | 1,165 ms | 2,280 ms | 4,025 ms |
| NIST p × (N + 1) (NumPy “weibull”) | 1,165 ms | 3,720 ms | 6,275 ms |
P50 barely moves. P90 ranges from 2,100 to 3,720 ms, a 1.6 second spread from the same 20 numbers. The methods split in the tail because only a couple of values sit there, so each formula interpolates across a wide gap.
The fix costs nothing: report the method and N with every percentile, and compare percentiles only across the same method. As the sample grows, neighboring values sit closer together and the methods converge.
Why averages mislead: mean vs P50
The mean adds every value and divides by the count. Take 20 illustrative voice agent turns: 16 finish in 1,450 ms or less, and the other four take 1,600, 2,100, 3,900 and 6,400 ms. They sum to 31,700 ms, so the mean is 31,700 ÷ 20 = 1,585 ms.
The median is 1,150 to 1,165 ms depending on the method, and 16 of the 20 turns were faster than the mean. The “average” turn described almost no caller’s experience.
The tail pulls the mean around. Replace the 6,400 ms turn with 2,400 ms and the mean drops 200 ms, to 1,385 ms. P50 does not change at all, and the nearest-rank P95 falls from 3,900 to 2,400 ms. The percentiles tell you exactly where the improvement happened, while the mean only tells you that something changed.
Google’s site reliability engineers reach the same conclusion. The SRE book’s chapter on service level objectives says “We generally prefer to work with percentiles rather than the mean (arithmetic average) of a set of values.” It also warns that computing systems produce skewed data, so the mean and median can sit far apart.
Averages still have a job. Sums and counts add up across servers and time windows, so a mean combines cleanly. That suits capacity planning and spotting a slowdown that hits every request. Track it, but set user-facing targets on percentiles.
How many measurements do P90 and P95 need?
A percentile is only as stable as the number of values beyond it. At N measurements, about N × (1 − p) values sit above the pth percentile. At 20 turns that is two values above P90 and one above P95, so a single slow turn can move either one by seconds.
A working rule of thumb, not a statistical law: wait until at least 10 measurements sit above a percentile before you trust it. That means about 100 measurements for P90, 200 for P95 and 1,000 for P99. Below those volumes, report the lower percentile and say why.
Three habits keep tail percentiles honest:
- Measure per turn, not per call. A 100-call day at 12 turns per call yields 1,200 turn measurements, enough for a steady P95. Measured per call, the same day gives you 100 values, barely enough for P90.
- Never average percentiles. Take 20 illustrative turns: 18 between 820 and 2,100 ms in a busy hour, and two of 3,900 and 6,400 ms in a quiet hour. The nearest-rank P90s are 1,600 ms and 6,400 ms, and their average is 4,000 ms. The true P90 of all 20 turns is 2,100 ms. Keep raw values, or fine-grained histogram buckets, and compute the percentile over the combined data.
- Never add stage percentiles. Suppose a turn has only two stages, across 20 turns. Speech-to-text takes 100 ms except on two turns that take 500 ms, and the model takes 600 ms except on two other turns that take 2,000 ms. The nearest-rank stage P95s are 500 ms and 2,000 ms, which sum to 2,500 ms. The P95 of the whole turn is 2,100 ms, because the slow stages rarely land on the same turn. Measure the full turn first, then break slow turns down by stage.
These habits cost something: raw values and fine buckets take storage, and coarse buckets save it but blur the tail you care about.
Why voice agents report latency at P50 and P90
Voice agents report latency at P50 and P90 because a caller waits through every turn of a call, not through one request. In a voice agent, a turn’s latency is the gap between the moment the caller stops speaking and the moment the agent starts. The caller hears that gap as silence, with no spinner or progress bar to explain it.
A call strings many turns together, so the tail reaches far more calls than the percentile suggests. If turns were independent, a 10-turn call would contain at least one turn slower than P90 in 1 − 0.9^10 ≈ 65% of calls. A turn slower than P95 would appear in about 40% of 10-turn calls.
Real turns within a call are correlated, so treat these as illustrations rather than forecasts. They still show why P90 is a delay many callers actually hear.
That gives each percentile a clear job:
- P50 shows the pace of a normal exchange. Use it to compare two models, prompts or providers on speed.
- P90 shows a delay that many calls meet at least once. Use it for release gates and vendor shortlists.
- P95 and P99 catch rare stalls, such as a hung tool call or a cold start, once you have the volume to measure them.
A turn’s latency comes from endpointing, speech-to-text finalization, model inference, any tool call, speech synthesis and the network path. A stage that is only sometimes slow, such as a tool lookup, shows up in P90 well before it moves the typical turn. The voice AI latency guide explains where each stage’s clock starts and stops.
What P50 vs P90 looks like in real voice benchmarks
Cekura’s public benchmarks report both typical and tail latency, which shows how far apart the two sit in practice.
Speech-to-speech models: median vs P90 response time
Cekura’s speech-to-speech benchmark runs 12 realtime voice models and a cascade baseline through the same Pipecat agent, prompt and tools over live WebRTC calls. Each configuration runs 82 scenarios, three times each, and only the realtime model changes. Response time runs from the caller finishing to the agent starting to reply, and the leaderboard reports it per turn: the median is the typical turn and P95 is the slowest turn in twenty. Selected results from the Oct 14, 2026 update, with P95 taken from the response time table on each model page:
| Model (leaderboard name) | Median response time | Response time, P90 | Response time, P95 | P90 minus median |
|---|---|---|---|---|
| Grok Voice 3.0 | 1.34 s | 1.62 s | 1.74 s | 0.28 s |
| Phonic v1 | 1.60 s | 1.88 s | 1.96 s | 0.28 s |
| Azure Realtime | 1.66 s | 2.22 s | 2.42 s | 0.56 s |
| Gemini 3.8 Live | 1.91 s | 2.23 s | 2.43 s | 0.32 s |
| GPT Realtime 2.1 | 1.94 s | 2.46 s | 2.64 s | 0.52 s |
| GPT-Live 1 + GPT-6 Sol | 2.02 s | 2.42 s | 2.59 s | 0.40 s |
| Cascade | 2.17 s | 2.51 s | 2.62 s | 0.34 s |
| Gemini 3.1 Flash Live Preview | 2.88 s | 4.00 s | 4.41 s | 1.12 s |
Four findings matter for a shortlist:
- Azure Realtime is 0.25 s faster than Gemini 3.8 Live at the median, but the two sit 0.01 s apart at P90.
- GPT-Live 1 + GPT-6 Sol is slower than GPT Realtime 2.1 on typical replies (2.02 s vs 1.94 s) and faster at P90 (2.42 s vs 2.46 s).
- Across all 13 configurations, P90 ran 1.16 to 1.39 times the median. Gemini 3.1 Flash Live Preview had the widest gap, at 1.12 s.
- Gemini 3.1 Flash Live Preview’s P95 is 4.41 s, 1.5 times its median.
These calls run over WebRTC on a fixed reference agent, not phone lines, with each model on the settings listed on its leaderboard card. Those settings include turn taking: most rows use the service’s own turn detection, Gemini 3.1 Flash Live Preview and Amazon Nova 2 Sonic use a shared local turn detector, and the Cascade uses speech-to-text turn detection. Your stack, prompt and network will differ. The leaderboard also ranks reliability by pass³ separately, and the fastest model is not automatically the right one.
Speech-to-text models: P50, P90 and P95 final-text delay
Cekura’s Converse-STT benchmark times final-text delay: how long after the caller stops until the full transcript arrives. A voice agent waits for this before it replies, so it is one stage of a turn rather than the whole turn. The benchmark reports P50, P90 and P95 per turn for 19 models, and the figures below were read from the live leaderboard on 24 October 2026.
| Model | P50 | P90 | P95 |
|---|---|---|---|
| Soniox STT-RT v5 | 38 ms | 72 ms | 79 ms |
| AssemblyAI Universal 3.6 Pro | 91 ms | 210 ms | 232 ms |
| Deepgram Flux English | 108 ms | 132 ms | 141 ms |
| Cartesia Ink 2 | 123 ms | 139 ms | 145 ms |
| Smallest Pulse | 201 ms | 356 ms | 773 ms |
| Reson8 | 235 ms | 357 ms | 398 ms |
- Smallest Pulse beats Reson8 by 34 ms at P50 and trails it by 375 ms at P95.
- AssemblyAI Universal 3.6 Pro is 17 ms faster than Deepgram Flux English at P50 and 91 ms slower at P95.
- Smallest Pulse’s P95 is 3.8 times its P50, while Cartesia Ink 2’s is 1.2 times.
A shortlist built on P50 alone ranks these models differently from one built on P95. All 19 models heard the same audio, 1,000 public clips plus real phone recordings licensed from Ocular, and speed was timed on the same streamed turns. Final-text delay leaves out inference, synthesis and network time, and the leaderboard ranks by word error rate, not speed.
How Cekura measures P50 and P90 latency for your agent
Cekura tests, monitors and self-improves voice and chat agents. Cekura’s Latency metric reports per-turn response time as a distribution, so you see the tail for your own agent rather than an average.
What the Latency metric reports
- Cekura measures latency from the recorded call audio. It times the gap between the end of the caller’s speech and the agent’s first audible response, using voice activity detection on a stereo recording (predefined metrics docs).
- Cekura calculates latency for every agent turn and computes P25, P50, P75, P90, P95 and P99. The metric’s headline result is an average in milliseconds, so read the percentiles next to it.
- The measurement happens on the audio channel, so it works the same way for cascaded, half-cascade and speech-to-speech agents. It includes endpointing, inference, synthesis and audio delivery, and it does not count caller-side silence as agent latency.
- The docs list the Latency metric at 0 credits and describe latency under 2,000 ms as generally good. Treat that as a starting threshold and tighten it for your use case.
Getting enough turns before and after launch
Before launch, you need enough turns for a stable tail percentile. Cekura runs scenarios as simulated calls, and its Infrastructure Suite adds 18+ prebuilt test cases covering latency, audio quality, interruption handling, language support and edge cases. Simulated minutes cost money: at the pay-as-you-go rate of $0.25 per voice testing minute, 20 scenarios of 3-minute calls run three times come to 180 minutes, or $45 before any paid metrics.
After launch, Cekura monitors production calls at $0.05 per monitored call, so the same per-turn latency comes from real traffic. Queueing tends to hit the tail first, so pair this with concurrent voice load testing before a traffic spike.
Cekura’s custom dashboard widgets have a limit worth knowing: they aggregate with count, sum, average, minimum and maximum. When you compare a dashboard trend against a percentile target, check that you are reading a percentile and not an average.
Where to start with P50 and P90
You do not need P99 on day one. Start with three steps:
- Log every turn’s latency as a raw value, from end of caller speech to start of agent speech.
- Report P50 and P90 per release, with N and the percentile method written next to each.
- Gate releases on P90, and add P95 once you have about 200 turns per comparison.
To see these numbers for your own agent before callers do, book a demo or start free with 300 credits.
Frequently asked questions
What does P50 mean in latency?
P50 latency is the median response time: half of requests or turns finish at or below it and half take longer. It describes the typical experience. Pair it with P90 or P95, because the middle value does not change when only the slowest 10% of responses get slower.
Is P50 the same as the average?
No. P50 is the middle value after sorting, while the average (mean) is the sum divided by the count. Latency data is usually skewed by a few slow responses, so the mean sits above the middle value. In 20 illustrative turns running from 820 to 6,400 ms, the mean is 1,585 ms and the median is 1,150 to 1,165 ms, depending on the method.
What is the difference between P90 and P95?
P90 is the value 90% of measurements stay at or below, and P95 is the value 95% stay at or below. P95 sits further into the slow tail, so it catches rarer delays. It needs about twice the data: roughly 200 measurements against 100 for at least 10 values above it.
Is a higher P90 good or bad?
In latency, a higher P90 is bad, because the slowest 10% of responses got slower. In oil, gas and solar forecasts, P90 is the estimate the real outcome equals or beats 90% of the time, so a higher value means a larger conservative estimate. If a report’s P90 is lower than its P50, it uses the forecast convention.
What is a good P50, P90 and P95 latency for a voice agent?
There is no universal target, but Cekura’s docs describe agent latency under 2,000 ms as generally good. On Cekura’s speech-to-speech benchmark, the fastest realtime model replied in 1.34 s at the median, 1.62 s at P90 and 1.74 s at P95. That was on a fixed reference agent over WebRTC. Set your targets from your own turns.
How do you calculate P90 in Python?
Call numpy.percentile(values, 90). NumPy uses linear interpolation by default, and method=“inverted_cdf” gives the nearest-rank answer instead. On small samples the methods can differ by more than a second, so record which method you used and how many values went in.