The datasets for training and evaluating RAG models split into three jobs: training or choosing the retriever (MS MARCO, Natural Questions), comparing embedding models (BEIR, MTEB), and testing the whole pipeline (HotpotQA, RGB, CRAG, FRAMES). Public sets are good for picking parts. Only a test set built from your own documents and real queries tells you whether the system works.
Last updated: October 2026 · By Atul Jain
What datasets for training and evaluating RAG models are actually for
A retrieval-augmented generation (RAG) system has two moving parts. A retriever finds passages in your knowledge base, and a generator writes an answer from them. Each part can fail on its own, and the data you need depends on which part you are testing.
That gives you three different dataset jobs:
| Job | What the data must contain | Typical public sets |
|---|---|---|
| Train or fine-tune a retriever | Queries paired with relevant passages, ideally with hard negatives | MS MARCO, Natural Questions |
| Choose an embedding model | Many retrieval tasks across domains, scored the same way | BEIR, MTEB |
| Evaluate the full pipeline | (context, query, answer) triplets, plus questions with no answer | HotpotQA, RGB, CRAG, FRAMES |
Teams often mix these jobs up. A retriever that scores well on a training set has learned that set. A generator that scores well on an end-to-end benchmark has been tested on Wikipedia, not on your returns policy.
Keep one rule in mind. Never evaluate on data the model was trained or tuned on. If you fine-tune an embedding model on MS MARCO, MS MARCO numbers stop telling you anything about generalization.
RAG vs traditional language models: why the data looks different
A traditional language model stores what it knows in its weights. You evaluate it with question and answer pairs, because the only input is the question.
RAG changes the unit of evaluation. The paper that named the approach, Lewis et al. at NeurIPS 2020, combined a pre-trained sequence-to-sequence model (parametric memory) with a dense vector index of Wikipedia (non-parametric memory). It set the state of the art on three open-domain question answering benchmarks. It also reported generated text that was more specific, diverse and factual than a parametric-only baseline.
The data consequence is direct. Because the answer depends on what was retrieved, a RAG test case needs three fields, not two:
-
Context: the passage that contains, or should contain, the answer.
-
Query: the question a user actually asks.
-
Answer: what a correct response says.
The context field is what lets you score retrieval separately from generation. Without it, a wrong answer could mean the retriever missed the passage or the model ignored it, and you cannot tell which. The cost is labeling effort: someone has to mark which passage is the ground truth for each question.
If you are still deciding whether retrieval is the right fix at all, compare it with fine-tuning and prompt grounding first. The tradeoffs are laid out in this comparison of RAG grounding methods.
Datasets commonly used to train and evaluate RAG models
These are the datasets you will see most often in RAG papers and tooling. The figures come from each dataset's own paper or official card.
| Dataset | Main job | Size and shape | What it tests | The catch |
|---|---|---|---|---|
| MS MARCO | Retriever training | 1,010,916 anonymized Bing questions; 8,841,823 passages from 3,563,535 web documents | Passage ranking on real search queries | Web search intent, not enterprise documents |
| Natural Questions | Retriever training and QA | 307,373 training examples; 7,830 dev and 7,842 test examples with 5-way annotations | Real Google queries answered from Wikipedia | Wikipedia only |
| HotpotQA | End-to-end, multi-hop | 113k Wikipedia question and answer pairs that need multiple supporting documents | Combining evidence across documents | Heavily used, so models may have seen it |
| BEIR | Retriever comparison | 18 retrieval datasets across domains | Zero-shot retrieval outside the training domain | Retrieval only, no generation |
| MTEB | Embedding comparison | 58 datasets, 8 task types, 112 languages | Embedding quality across tasks | Retrieval is one task among eight |
| RGB | Generator robustness | English and Chinese test sets | Noise robustness, negative rejection, information integration, counterfactual robustness | Tests the model given documents, not your retriever |
| CRAG | End-to-end | 4,409 question and answer pairs, 5 domains, 8 question categories, mock web and knowledge graph APIs | Long-tail and fast-changing facts | Built around search APIs, not a private corpus |
| FRAMES | End-to-end, multi-hop | 824 test questions, each needing 2 to 15 Wikipedia articles | Numerical, temporal and tabular reasoning across sources | Small; best as a stress test |
Two more multi-hop sets, 2WikiMultiHopQA and MuSiQue, are often paired with HotpotQA to check that a result holds beyond one dataset.
Read the table by the "main job" column first. Picking an end-to-end benchmark to choose an embedding model, or a retrieval benchmark to judge answer quality, measures the wrong thing.
Training data: what you can actually train in a RAG pipeline
You will rarely train a RAG model from scratch. You choose an embedding model, a reranker and a generator, then tune the pieces that matter. Training data matters most in two places.
The retriever. Retriever training needs queries paired with passages that answer them. MS MARCO and Natural Questions dominate here because they are large and built from real search queries. Ready-made training versions exist: the IBM researchers behind the "Know Your RAG" study (COLING 2025) used versions of HotpotQA and MS MARCO built to train Sentence Transformers models.
Fine-tuning a retriever on your own domain usually needs your own pairs. The cheapest source is your search or support logs: a query, and the document an agent or user ended up opening. The cost is cleaning. Logs carry personal data, duplicates and queries with no good answer.
The generator. You can fine-tune the generator to quote its sources and refuse when the context does not support an answer. That needs examples of both behaviours, including cases where the right output is "the documents do not say". Few public sets give you those refusal examples in your domain, so you will usually write them yourself.
What not to train on. Hold out every dataset you plan to report results on. If a public benchmark was part of a model's training mix, its score on that benchmark is not a fair measure. For widely used sets such as Natural Questions and HotpotQA, assume a large model may have seen them during pretraining, and weight your private test set more heavily.
Best embedding model for RAG: what the benchmarks can and cannot tell you
There is no single best embedding model for RAG, and the benchmark built to compare them says so. The MTEB paper (Muennighoff et al., EACL 2023) tested 33 models across 8 embedding tasks, 58 datasets and 112 languages. It found that no particular text embedding method dominates across all tasks.
BEIR, the retrieval benchmark that MTEB draws on, reached a related conclusion in 2021. Testing 10 retrieval systems across 18 datasets, its authors found BM25 keyword search to be a robust baseline. Reranking and late-interaction models achieved the best zero-shot results on average, at high computational cost.
Use those findings to shortlist, not to decide:
-
Filter the MTEB leaderboard to retrieval tasks. The overall average mixes in clustering and classification, which say little about RAG.
-
Shortlist three models across a cost range. Include one small, fast model and one larger one. Embedding dimension sets your vector storage cost, and model size sets query latency.
-
Keep BM25 or hybrid search as a baseline. If a dense model cannot beat keyword search on your queries, the extra infrastructure is not paying for itself.
-
Score each candidate on your own labeled queries. Use recall@k and mean reciprocal rank against the ground-truth passages in your test set.
-
Re-test when your documents change shape. A model that ranks well on prose can fall behind on tables, product codes or transcribed speech.
Step 4 is the one that decides. Leaderboard positions shift as new models are submitted, and none of the leaderboard's datasets is your corpus.
Why public benchmarks can mislead you on your own corpus
A strong public benchmark score is a necessary signal, not a sufficient one. Two studies show the gap from different sides.
The first is the Know Your RAG study from IBM Research, presented at COLING 2025. The authors labeled (context, query) pairs from six public datasets: HotpotQA, MS MARCO, Natural Questions, NewsQA, PubMedQA and SQuAD2. They sorted each pair into four classes:
-
fact_single: the context states one fact that answers the query.
-
summary: the answer requires summarizing the context.
-
reasoning: the answer is not stated but can be inferred.
-
unanswerable: the context neither states nor implies the answer.
Public datasets turned out to be heavily unbalanced across these classes, and retrieval performance differed significantly between them. The authors conclude that evaluating on public Q&A data can lead to non-optimal system design when the question mix does not match your users. They found the same imbalance in synthetic sets generated with simple LLM prompts.
The second is CRAG, from Meta researchers at NeurIPS 2024. On its 4,409 questions, the most advanced LLMs reached at most 34% accuracy alone. Adding retrieval in a straightforward way lifted that to 44%. State-of-the-art industry RAG solutions answered only 63% of questions without any hallucination.
Accuracy fell further on facts that change quickly, on less popular entities, and on complex questions.
Put together, the lesson is practical. Your users' questions have a shape, such as mostly single facts, mostly procedures, or many questions your documents cannot answer. A benchmark with a different shape will rank your design choices in a different order.
How to build your own RAG evaluation dataset
Your own test set is the one that should gate releases. Build it in this order.
-
Collect real queries first. Pull 100 to 300 questions from search logs, support tickets or call transcripts. Remove personal data before anything else. Real phrasing, typos and half-formed questions are the point.
-
Label each query by type. Use the four Know Your RAG classes, and record the mix. If 40% of real queries need a summary, your test set should be close to 40% summary.
-
Add questions your documents cannot answer. Synthetic generators work from your corpus, so they skew toward questions it can answer. In IBM's Know Your RAG tests, 95% of questions from a simple generation prompt were single-fact questions. Real users do not know what is in your data. RGB tests this as "negative rejection", and its authors found models struggle with it.
-
Mark the ground-truth context. For each answerable query, record which passage or passages hold the answer. This is what lets you score retrieval on its own.
-
Write the expected answer as criteria. "Mentions the 30-day window and the receipt requirement" is easier to grade consistently than a reference paragraph.
-
Top up with synthetic questions, then filter them. Generate from your documents to cover thin areas. Discard questions that are not grounded in the source, not useful to a real user, or not understandable on their own. Have a person review a sample of what survives.
-
Freeze and version the set. Re-scoring the same frozen set is how you compare a change in chunking, embedding model or prompt.
-
Grade with a mix of methods. Use exact metrics where you can (recall@k for retrieval) and a calibrated LLM-as-a-judge for answer quality. Open-source frameworks such as Ragas implement common RAG metrics, including faithfulness, response relevancy, context precision and context recall, but they still need your test set to score against. Spot-check any judge against human labels.
Budget for the labeling. Someone who knows the domain has to label every query and mark its ground-truth passage. That work is paid once, and every later evaluation run reuses it.
Evaluating voice RAG agents: the dataset needs audio
Most RAG evaluation assumes the query arrives as clean text. In a voice agent it does not. The caller's question passes through speech-to-text before the retriever ever sees it, so a transcription error becomes a retrieval error.
A 2026 preprint, Better Retrieval, Worse Robustness, measured how far that error travels. It built 12,000 spoken queries from HotpotQA, 2WikiMultiHopQA and MuSiQue, synthesized in four English accents, and ran them through four RAG configurations. Three findings matter for dataset design:
-
More complex retrieval amplified the damage. The F1 gap between clean text and the highest-error accent was 36% to 67% larger for the most complex pipeline than for basic dense retrieval, on all three benchmarks.
-
Named entities were the failure point. Corrupted entity names in the transcribed query accounted for 87% to 96% of degraded cases on 2WikiMultiHopQA.
-
Synthetic speech understated real errors. On 500 real Nigerian-accented utterances, word error rate averaged 28.9%. The synthesized Nigerian-accented queries ran at 7.9% to 17.1% depending on the benchmark, so synthetic speech understated real transcription errors by 1.7 to 3.7 times.
The same gap between clean and real audio appears in Cekura's own measurements. Per Cekura's speech-to-text study on benchmarks.cekura.ai, 17 models were scored on 1,000 public voice-agent clips from Pipecat's dataset and on eight licensed recordings of real conversations. Word error rates on the public clips ranged from 1.77% to 6.48%.
On the real recordings, 14 of the 17 models had higher error rates. The model ranked first on the public clips placed 14th on the real conversations. GPT-4o Transcribe went from 3.90% on the clips to 12.45% on the recordings. The caveat travels with these numbers: the real-conversation set is only eight recordings from four conversations, so treat it as a signal, not a ranking.
For a voice RAG agent, this changes what belongs in the test set:
-
Spoken versions of every query, in the accents, speaking speeds and background conditions your callers actually have.
-
Entity-heavy questions on purpose: product names, policy numbers, drug names and street names are where transcription breaks retrieval.
-
Real recordings where you can get them, because synthesized speech gives you a lower error rate than production will.
Turning a knowledge base into spoken test calls
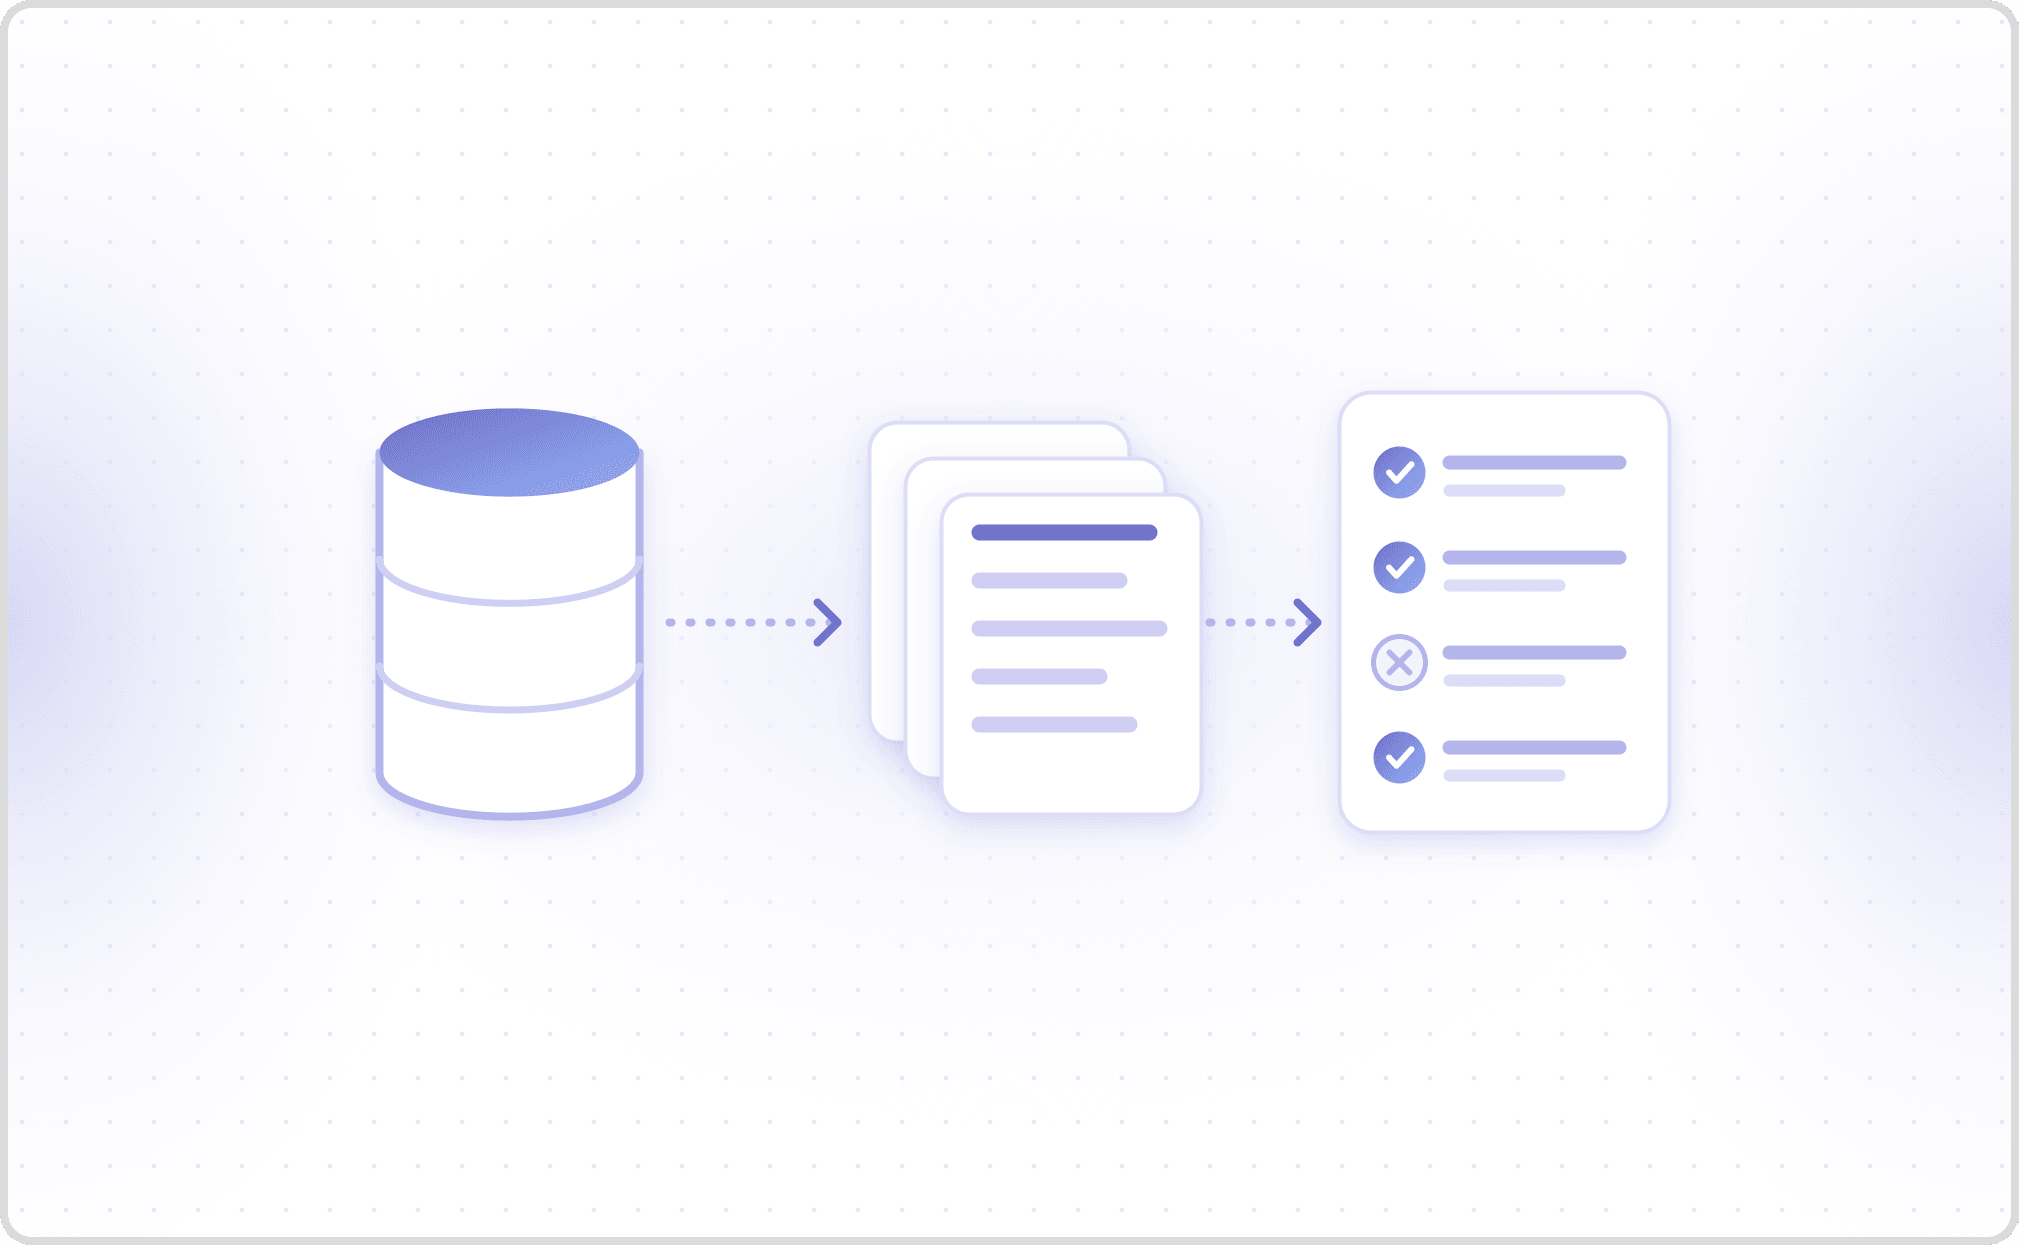
Cekura builds this kind of test set from your knowledge base. You upload your knowledge base files to the agent, and Cekura generates evaluators from them. Each evaluator has caller instructions that ask the questions a real user would ask, plus an expected outcome derived from the source document. Cekura then places a simulated call to your agent and scores the transcript against that expected outcome.
Cekura's caller personalities control the audio side of the dataset. Each personality sets the simulated caller's voice, accent, language, speaking pace, interruption behaviour and background noise. That lets one knowledge-base question run as a clean call, a fast call and a noisy call. Cekura's documentation also recommends replicating real call recordings, with personal data removed, as structured test cases.
To catch answers that drift from your documents, Cekura's Hallucination metric compares the agent's responses against the uploaded knowledge base files. It flags information that is unsupported by or contradicts them. The scoring is transcript-based: the metric checks what the agent said against the source, not what the retriever fetched. For the failure patterns behind that metric, see this guide to hallucination detection in voice AI.
Run each question more than once. Per Cekura's voice agent workflow benchmark, a frozen study of 8 configurations, 82 scenarios and 3 retained repeats, even the most reliable configuration, Retell, passed all three repeats in 62 of 82 scenarios (75.61%). One caveat applies: providers chose their own models, speech components and settings. A scenario that passes once has not shown it will pass again.
The same checks continue after launch. Cekura monitors production calls with the same metrics, so a question that starts failing after a knowledge base update shows up in live traffic as well as in test runs.
Frequently asked questions
What datasets are used to evaluate RAG models?
The most common are Natural Questions, MS MARCO and HotpotQA for question answering and retrieval, BEIR and MTEB for comparing retrievers and embeddings, and RGB, CRAG and FRAMES for end-to-end RAG behaviour. Use them to compare components. Use a test set built from your own documents and real queries to decide whether the system is ready.
How many questions should a RAG evaluation dataset have?
Start with 100 to 300 labeled questions drawn from real queries, with the mix of question types matching your traffic. That is enough to compare chunking or embedding changes. Grow it when you see failures the set does not cover, and add questions your documents cannot answer, because those are where systems fail.
Can I use synthetic data to evaluate a RAG system?
Yes, as a supplement. Generate questions from your documents, then discard any that are not grounded in the source, not useful, or not understandable on their own. IBM's Know Your RAG study found that 95% of questions from a simple generation prompt were single-fact questions. Write the unanswerable queries real users ask yourself.
What is the best embedding model for RAG?
No single model wins. The MTEB benchmark found no embedding method dominates across all tasks. Shortlist models from MTEB's retrieval results across a range of sizes, keep BM25 or hybrid search as a baseline, and choose by recall on your own labeled queries.
How is evaluating RAG different from evaluating a traditional language model?
A traditional model is tested with question and answer pairs. RAG needs (context, query, answer) triplets, because retrieval and generation fail separately. The context field lets you tell whether a wrong answer came from a missed passage or from a model that ignored the right one.
Build the test set before you tune anything
Public datasets help you choose parts. Your own frozen, versioned test set tells you whether the system works for your users, and for voice agents it has to include real audio. To see how Cekura turns your knowledge base into spoken test calls and keeps scoring them in production, book a demo with Cekura.